I am currently a research fellow at IMPL group, Singapore University of Technology and Design (SUTD), working closely with Prof. Na Zhao. Prior to joining SUTD, I completed my Ph.D. at PCALab group, Nanjing University of Science and Technology (NJUST), where I was fortunate to be advised by Prof. Jian Yang and Prof. Jun Li. I warmly welcome opportunities for discussion and collaboration—please feel free to reach out 😄.
Research
My research interests encompass computer vision and machine learning, with a focus on 3D-related tasks such as depth estimation, depth completion and 3D reconstruction, etc. These tasks play a pivotal role in various applications such as 3D scene understanding, AR/VR, robotics and autonomous driving etc.
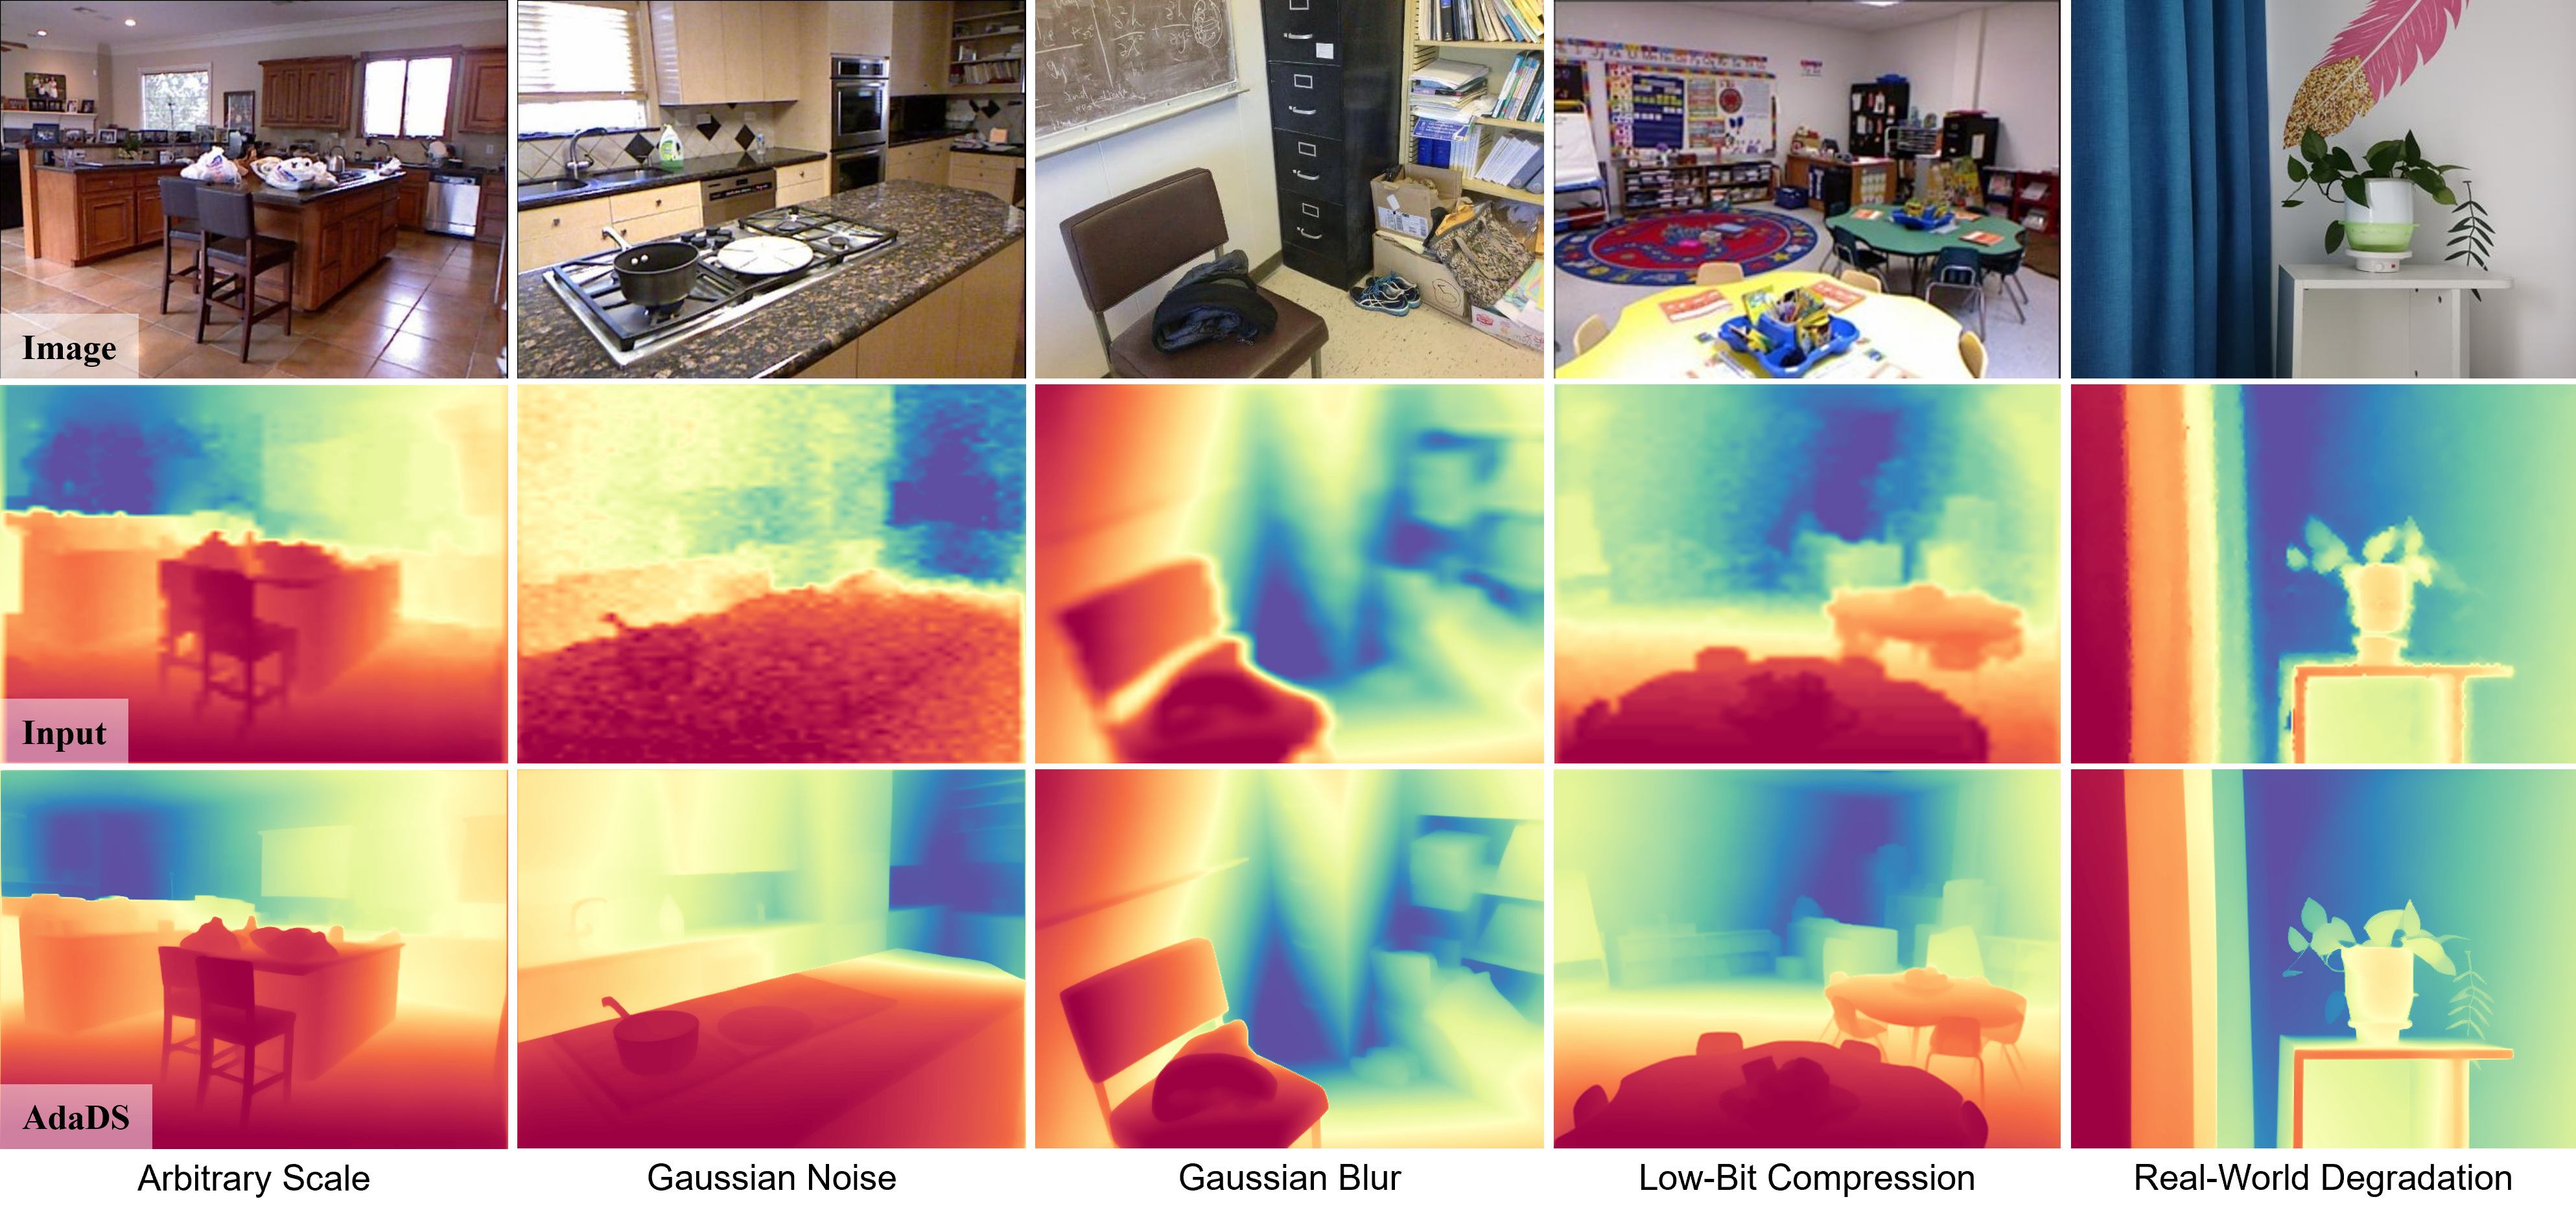
AdaDS estimates metric depth from arbitrarily degraded low-resolution depth prompts. Guided by prompt uncertainty, it adaptively selects a diffusion timestep and injects learned noise to project the coarse estimate into a high-density region of a pre-trained depth diffusion prior, which then corrects prompt errors for robust zero-shot depth estimation.
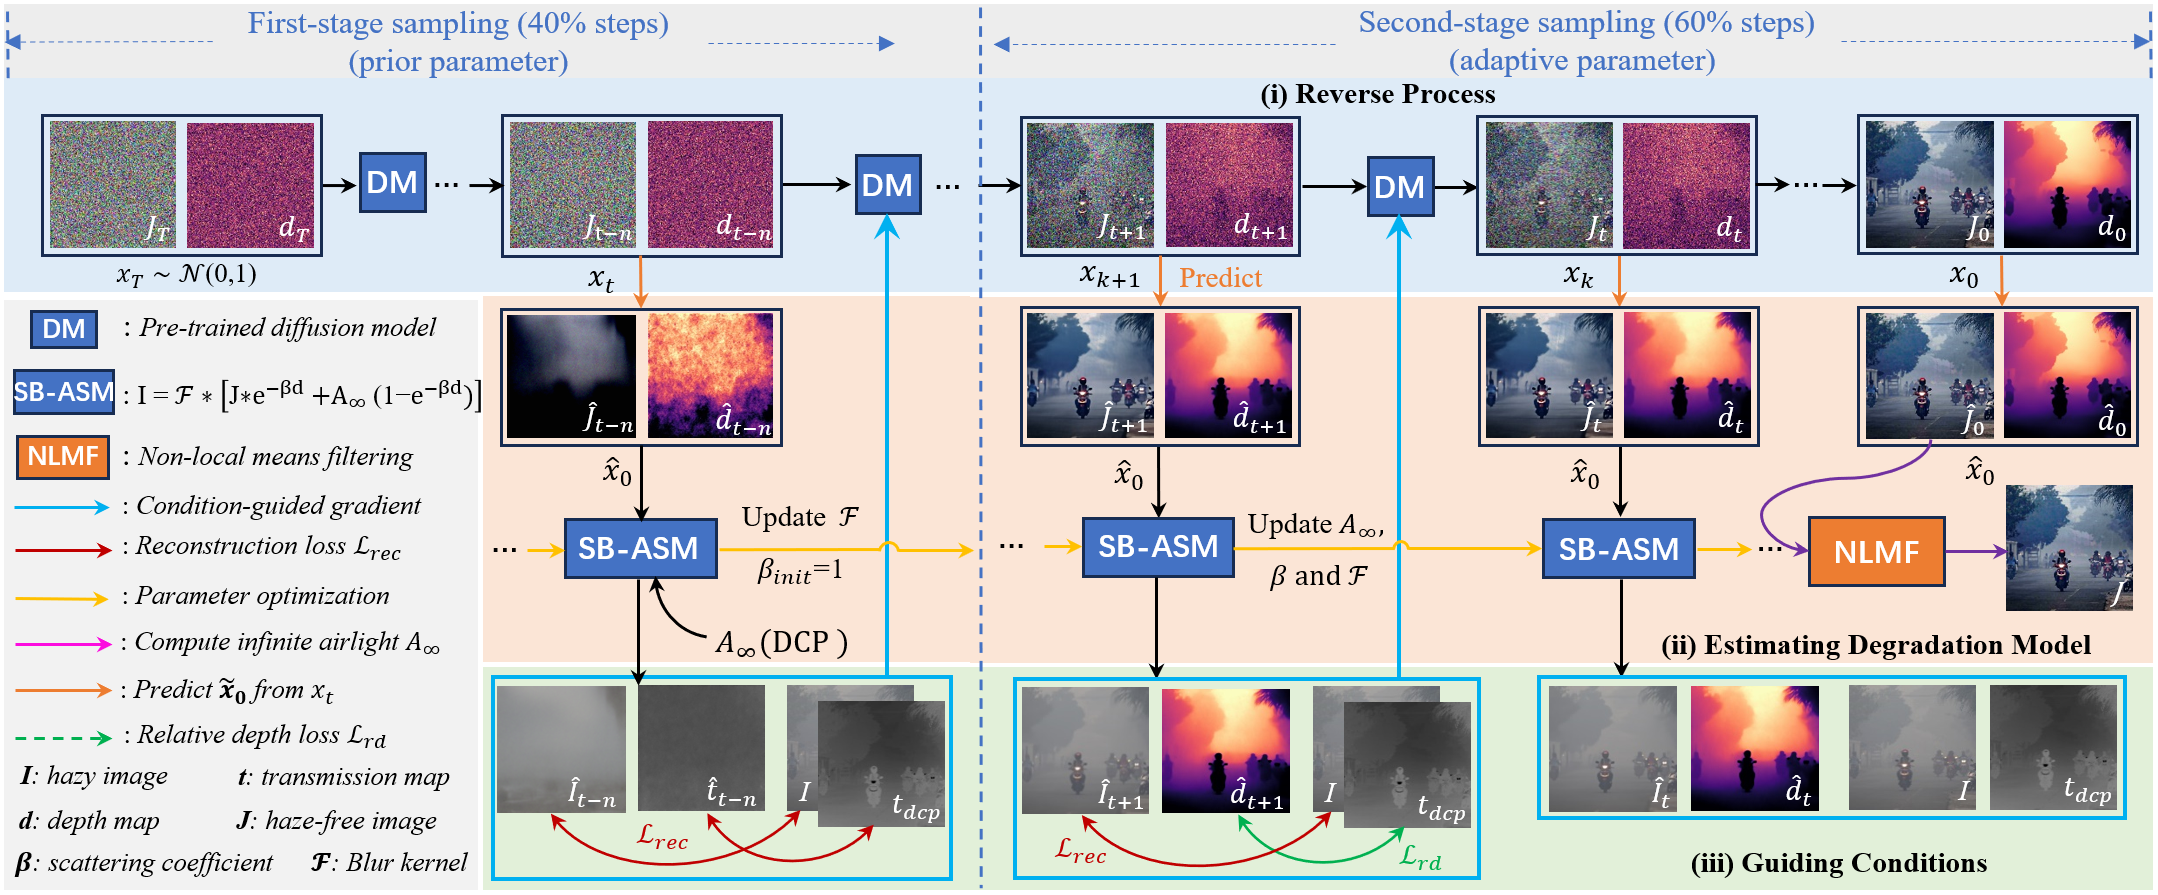
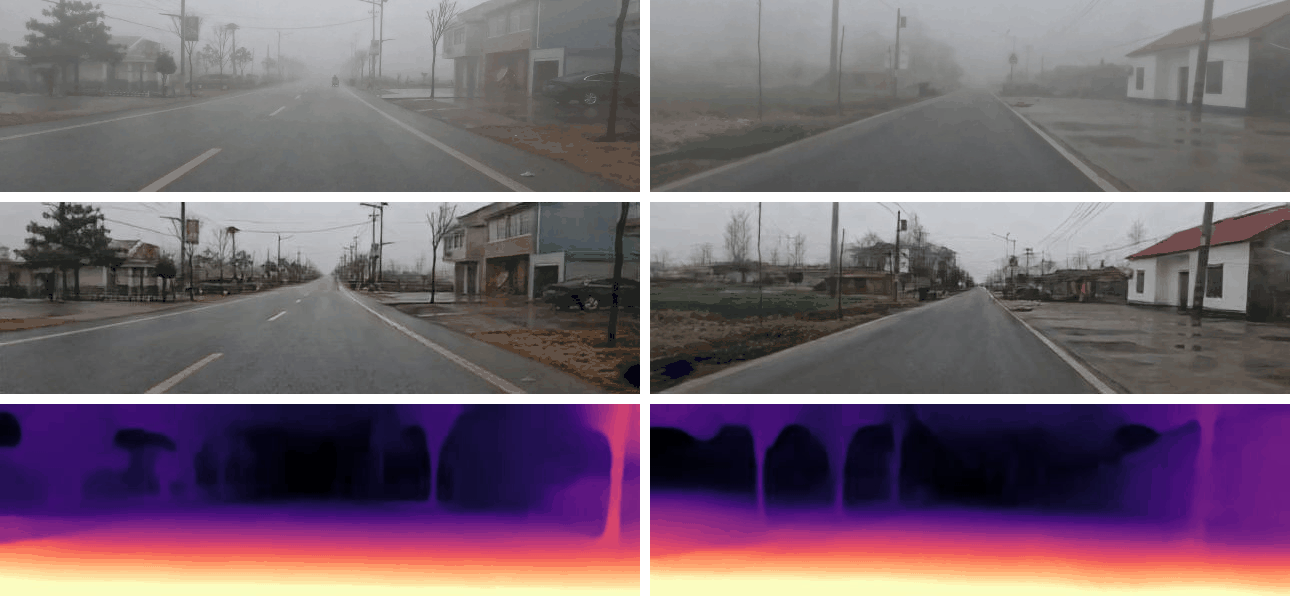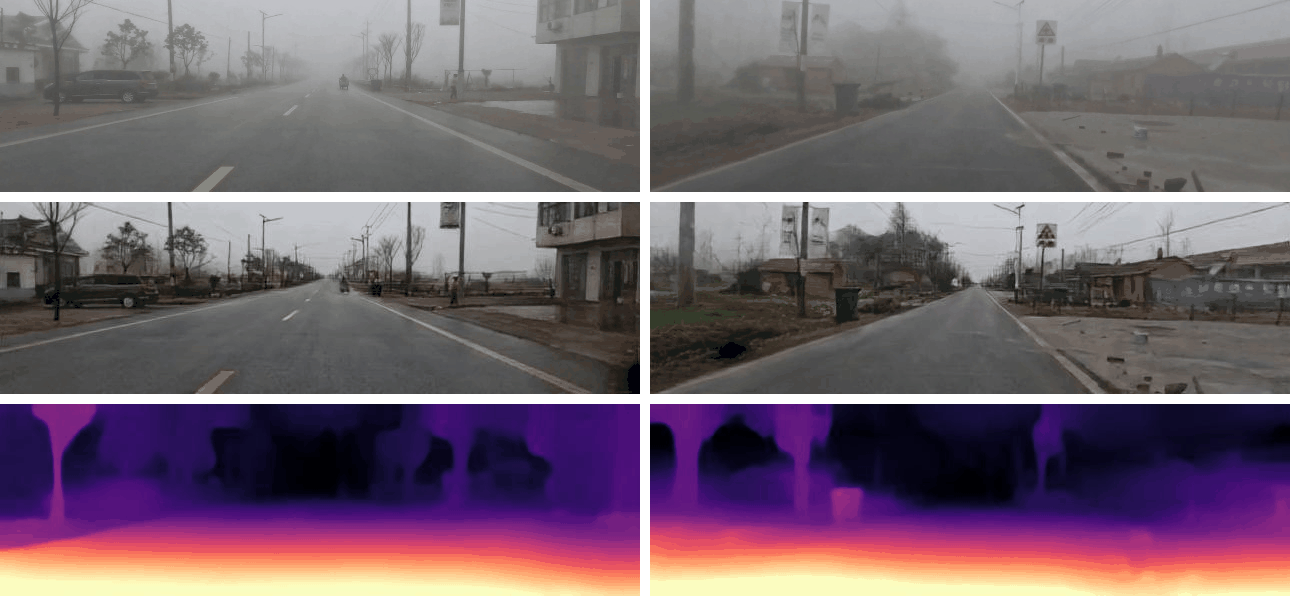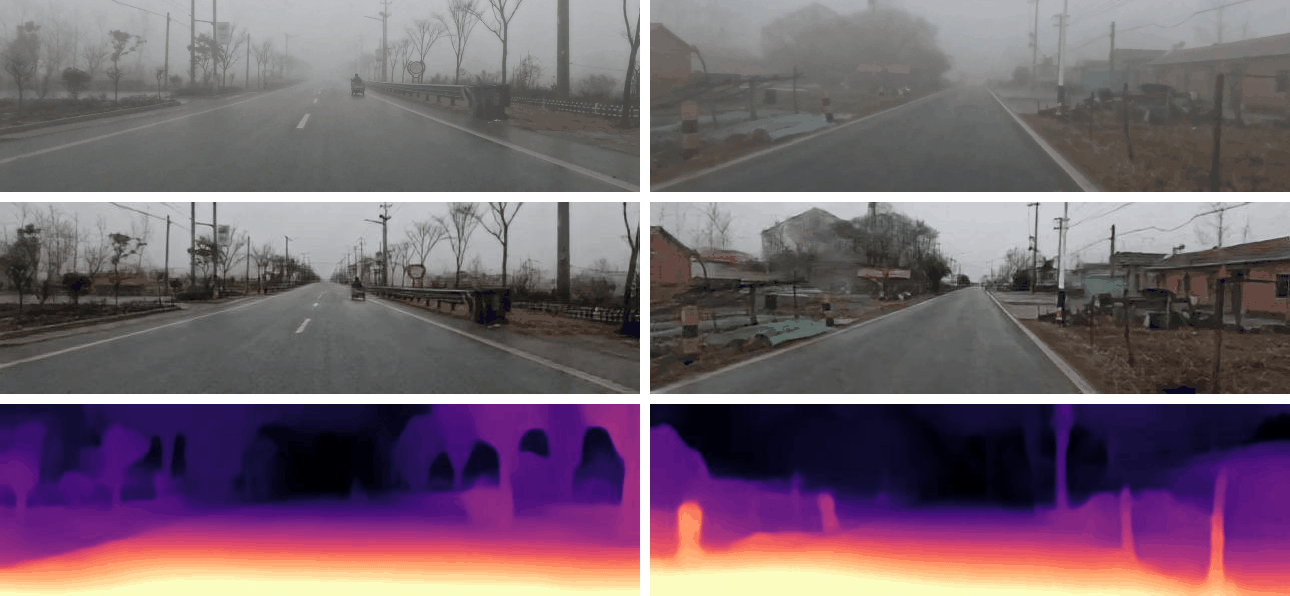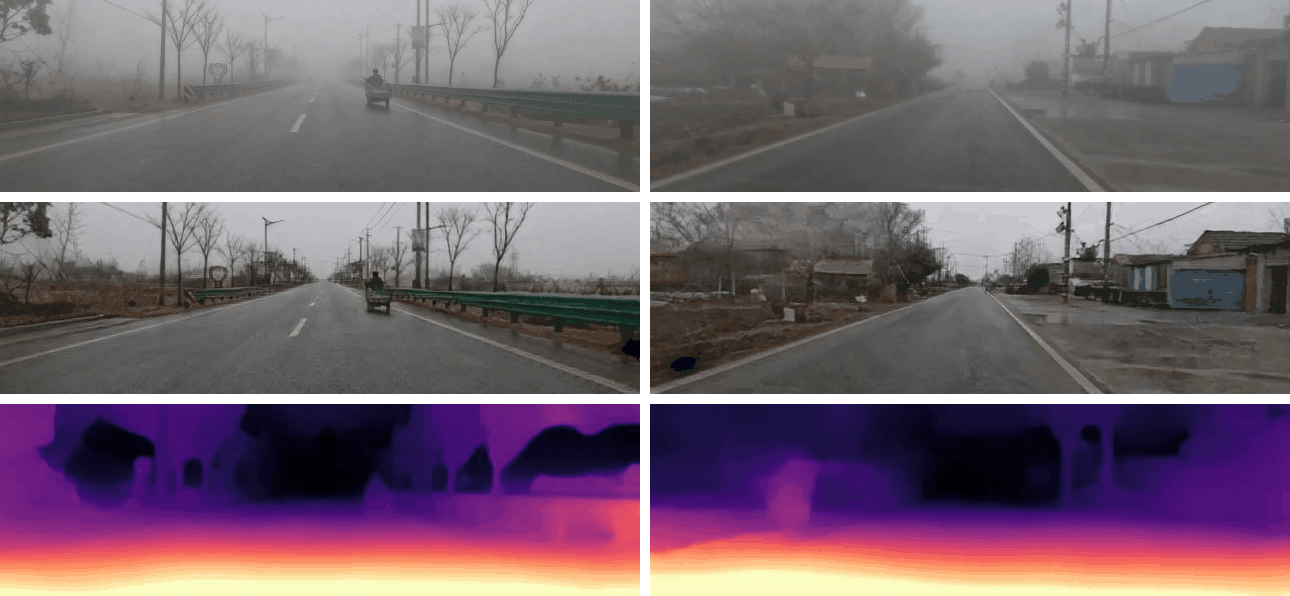
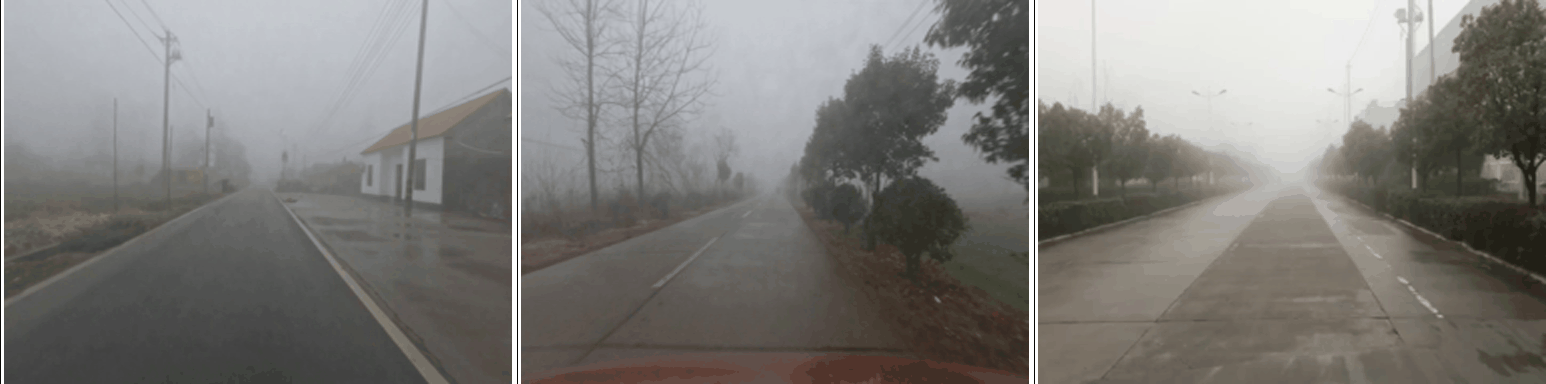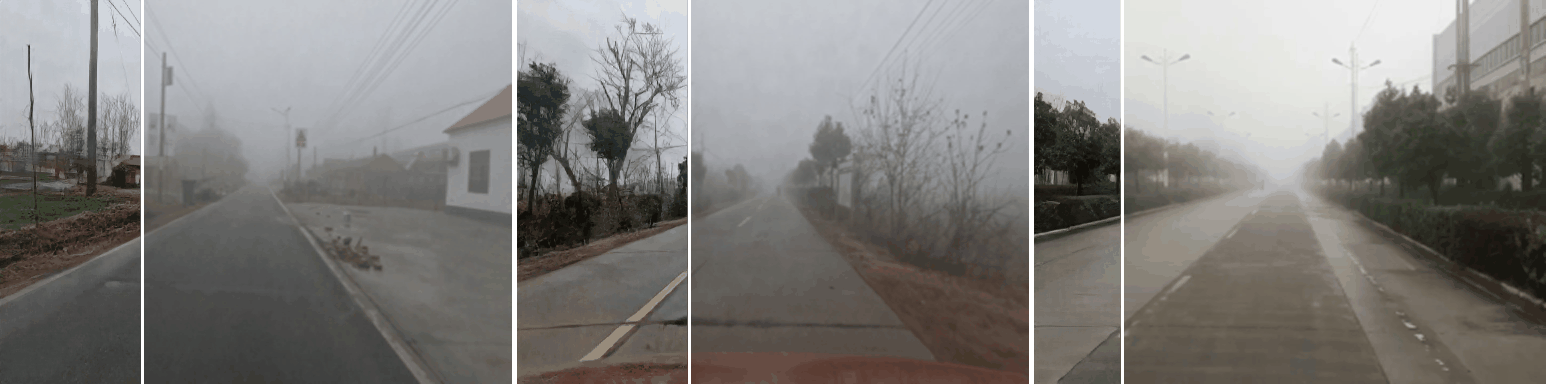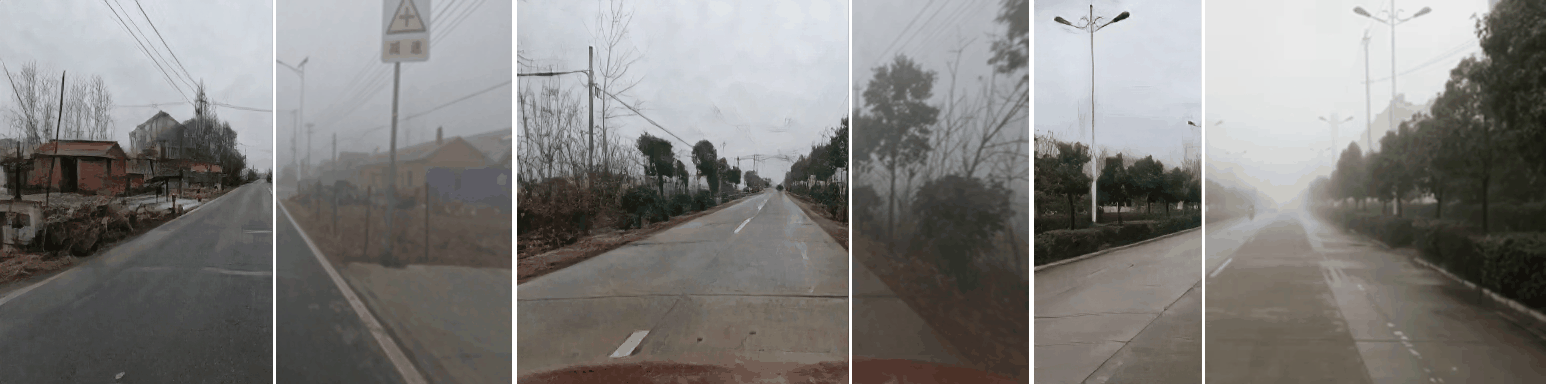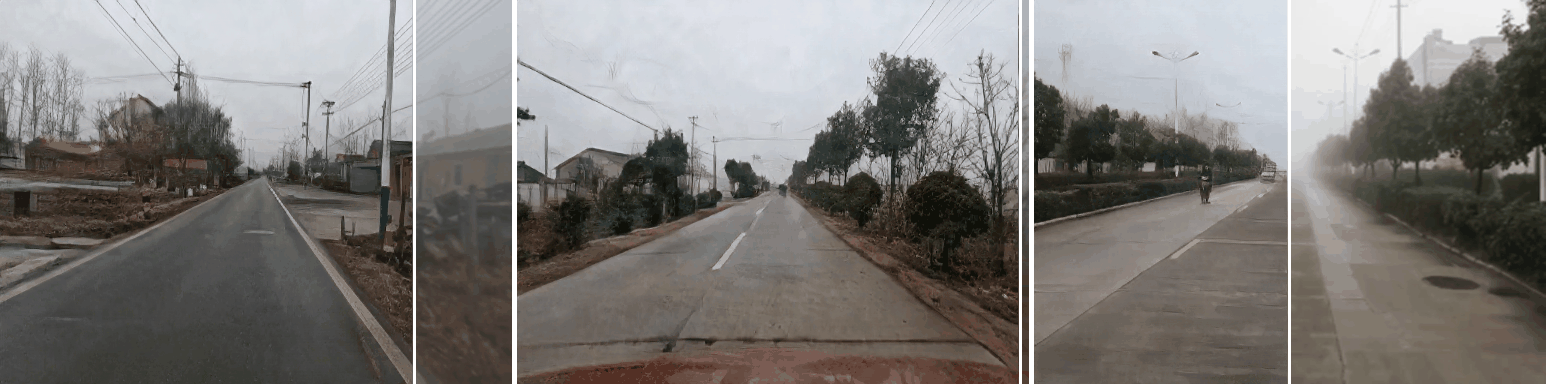
We propose a physics-guided diffusion model for dehazing that samples RGB and depth via a pre-trained diffusion process. It uses a hybrid degradation atmospheric scattering model to generate high-fidelity results without paired images, employs two-stage sampling with piecewise loss for improved quality and stability, and includes post-processing to remove amplified JPEG artifacts.
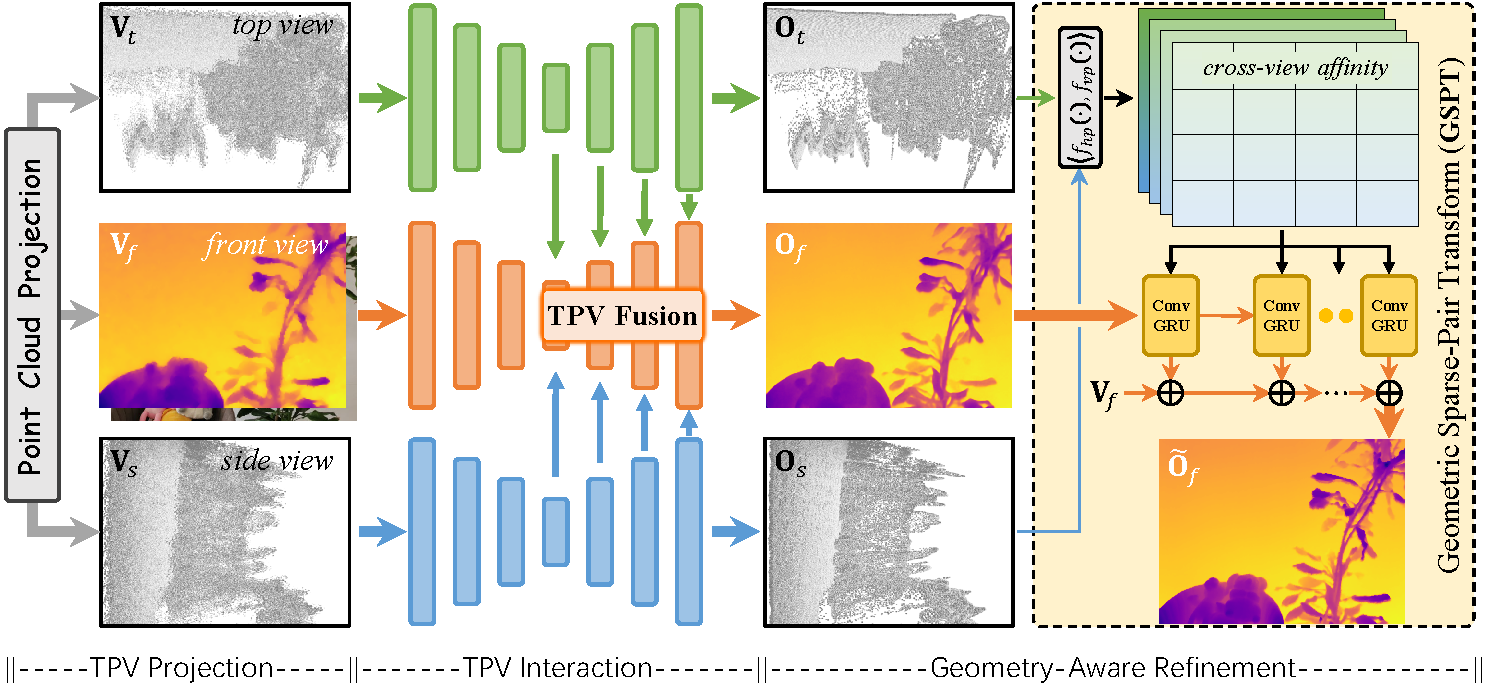
We expand its application from depth completion to depth super-resolution, both of which are RGB-D based depth perception tasks. We introduce 3D point clouds to explicitly model 3D geometry through TPV decomposition and GSPT refinement. We develop a large-scale dataset named TOFDSR. It is the second real-world DSR dataset and contains an order of magnitude more data than the first one.
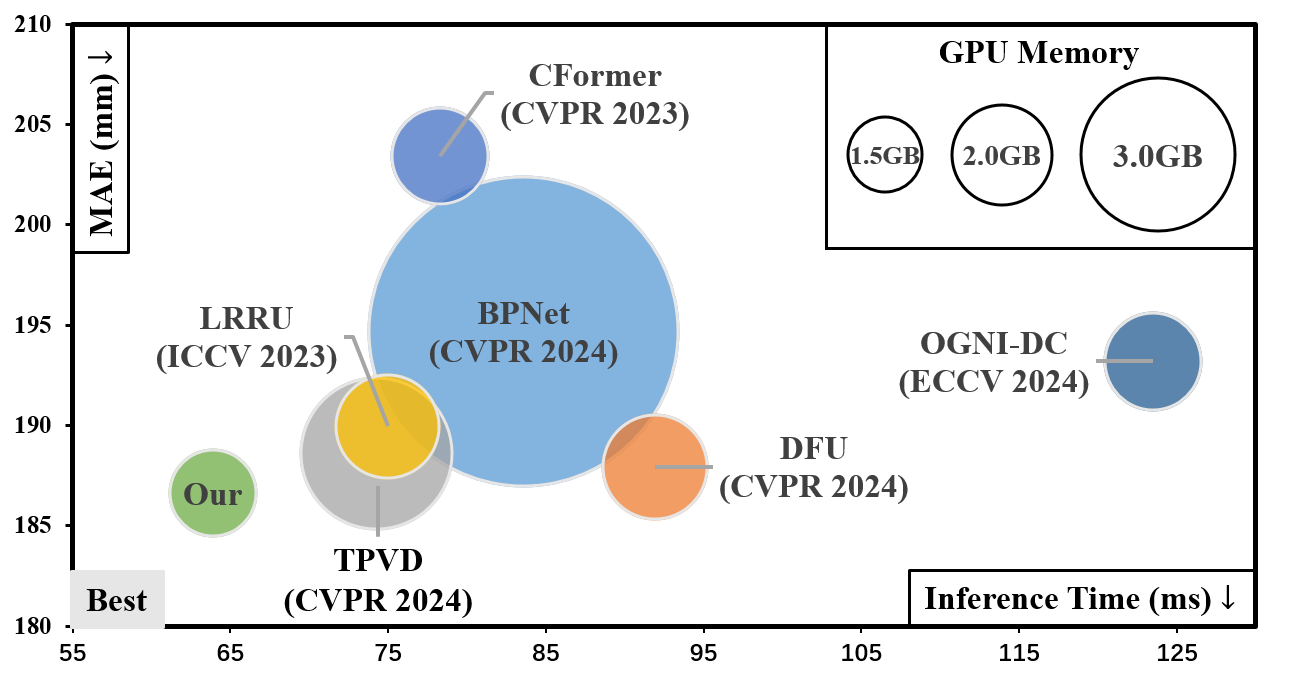
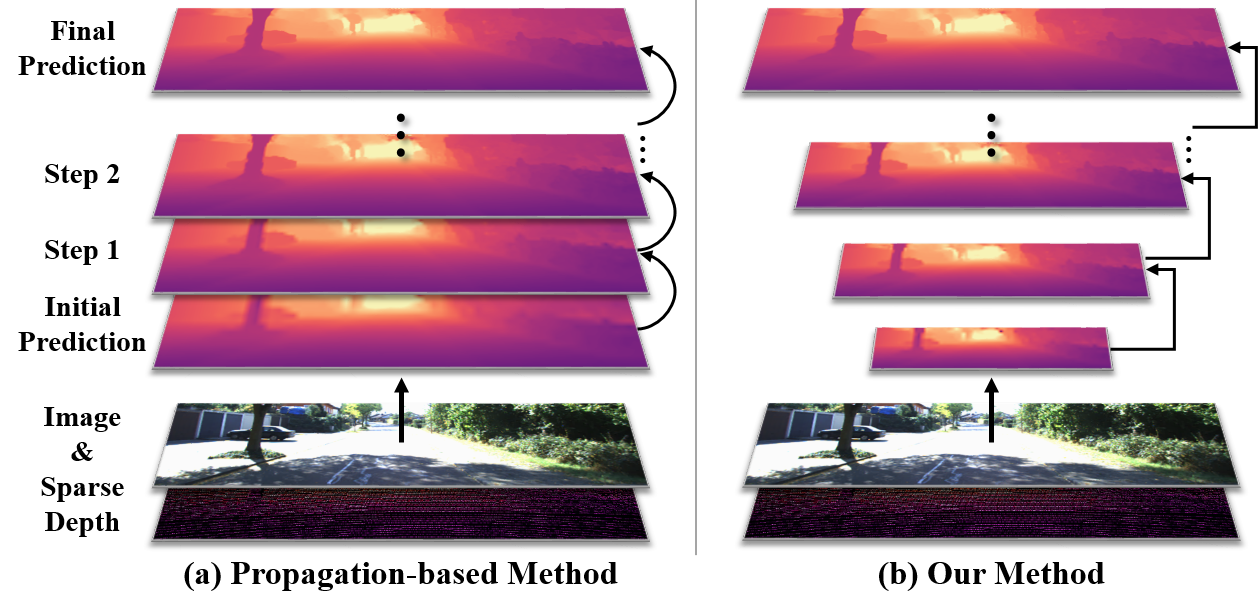
LP-Net introduces an innovative depth completion approach based on Laplacian Pyramid decomposition. It begins by establishing a global context of the scene structure, then progressively refines local details through a novel selective filtering mechanism at each scale. LP-Net achieves SOTA performance while maintains high computational efficiency. When this work was completed, it ranked 1st at KITTI online leaderboard among peer-reviewed methods.
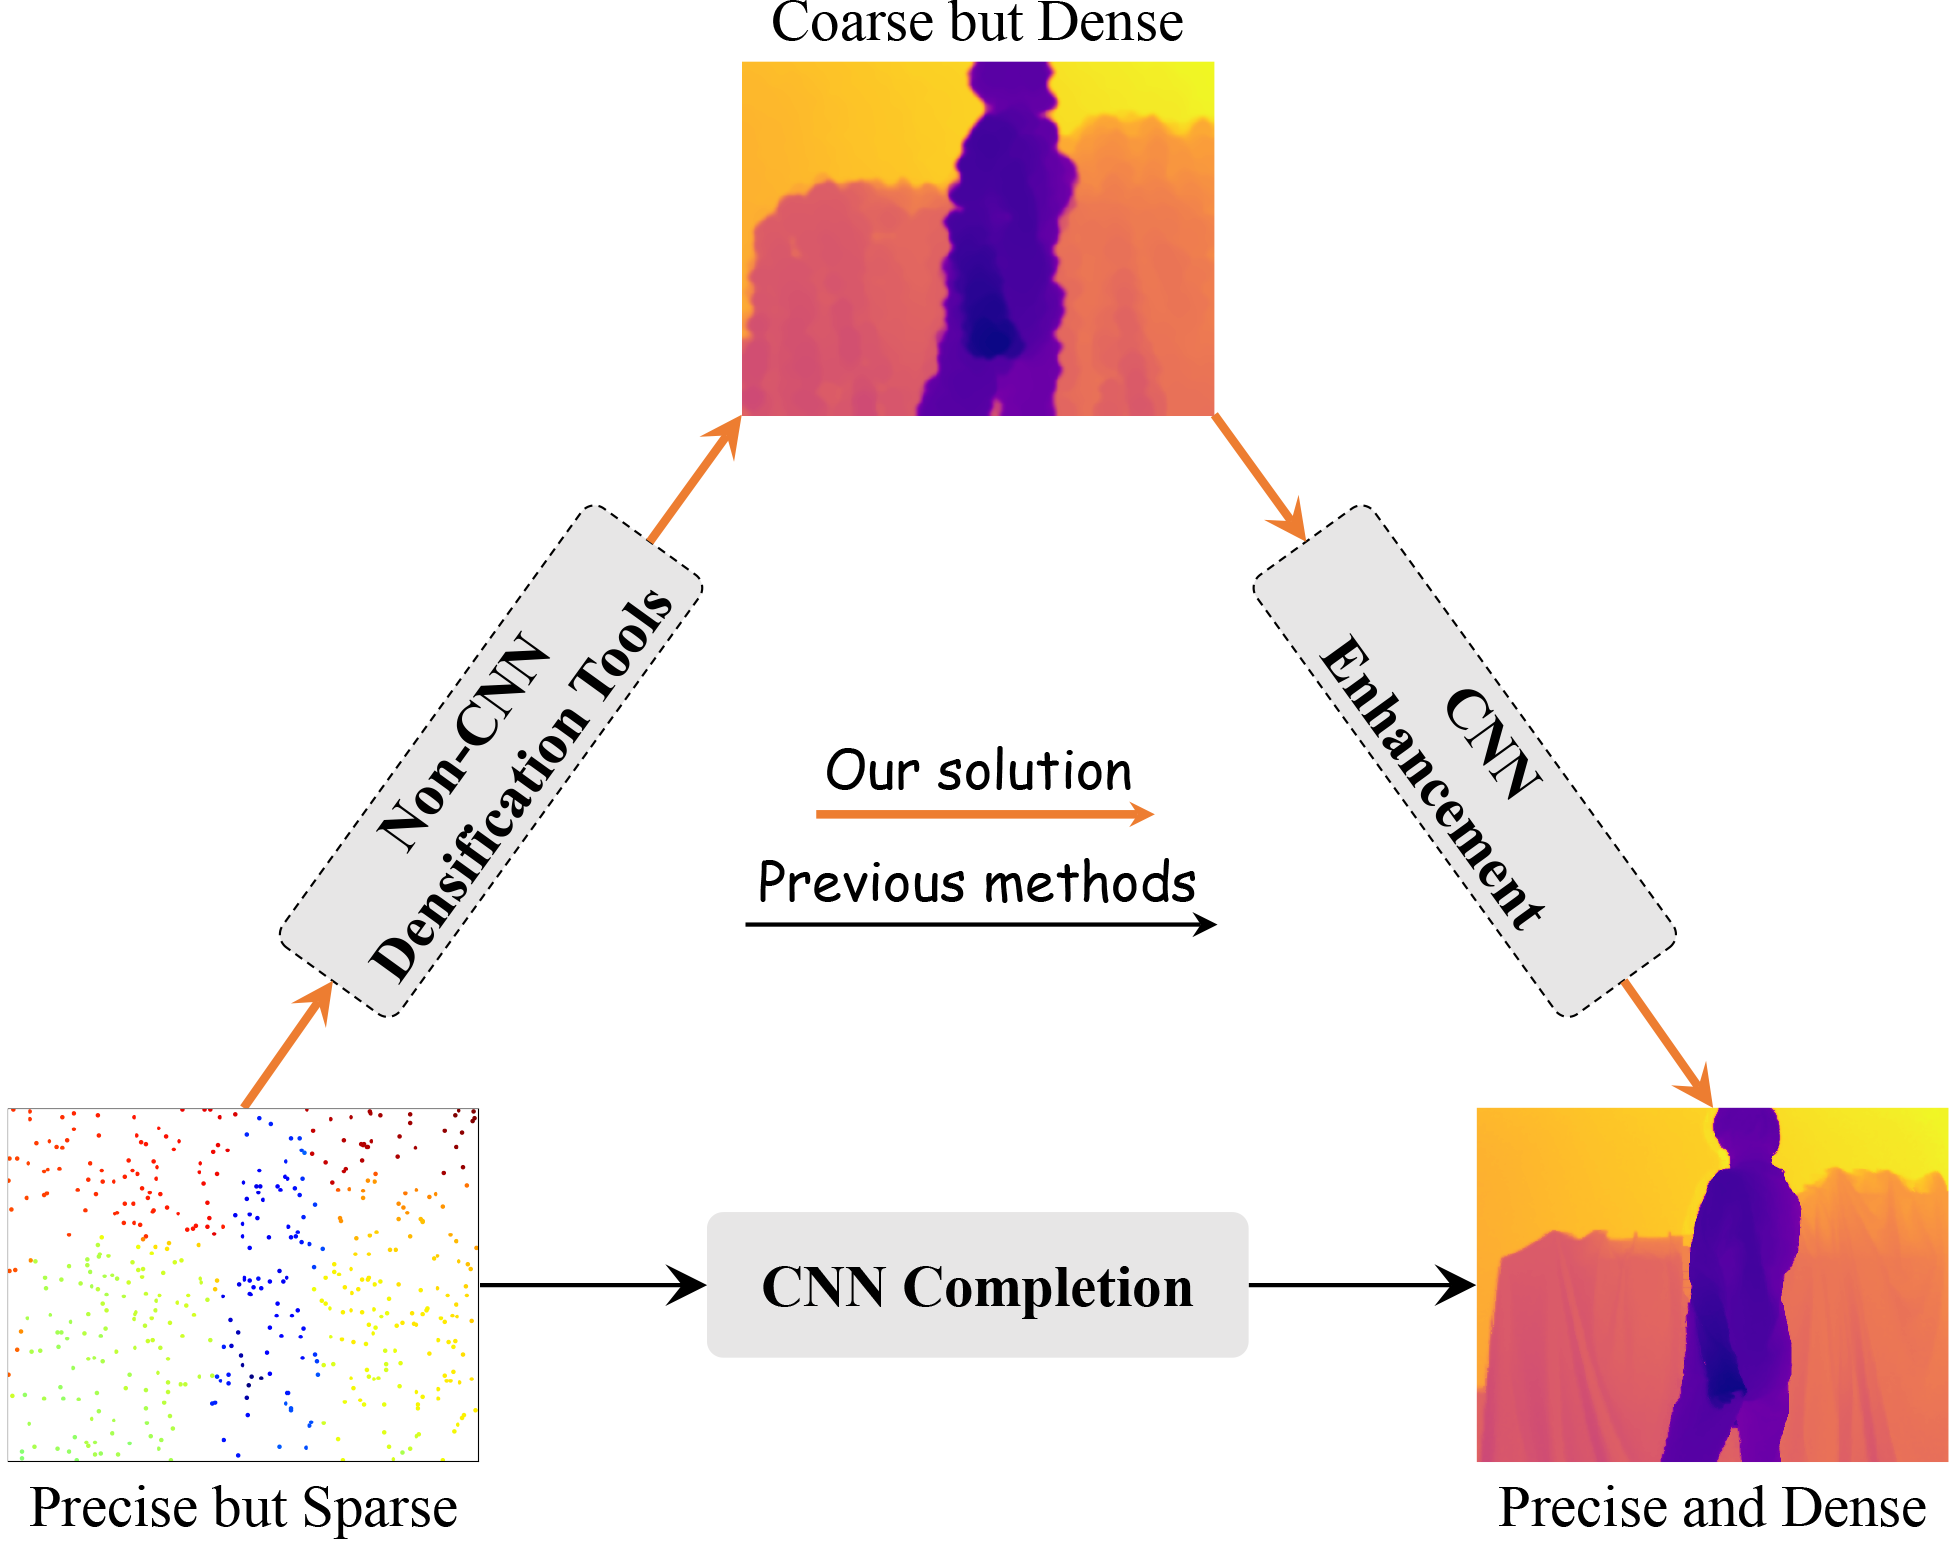
We propose a novel degradation-aware framework SigNet that transforms depth completion into depth enhancement for the first time. SigNet eliminates the mismatch and ambiguity caused by direct convolution over irregularly sampled sparse data. Meanwhile, it builds a self-supervised degradation bridge between coarse depth and targeted dense depth for effective RGB-D fusion.
We propose a novel depth-centric learning framework that combines the atmospheric scattering model(ASM) model with the brightness consistency constraint (BCC) constraint. The core idea is to use a shared depth estimation network for both ASM and BCC.
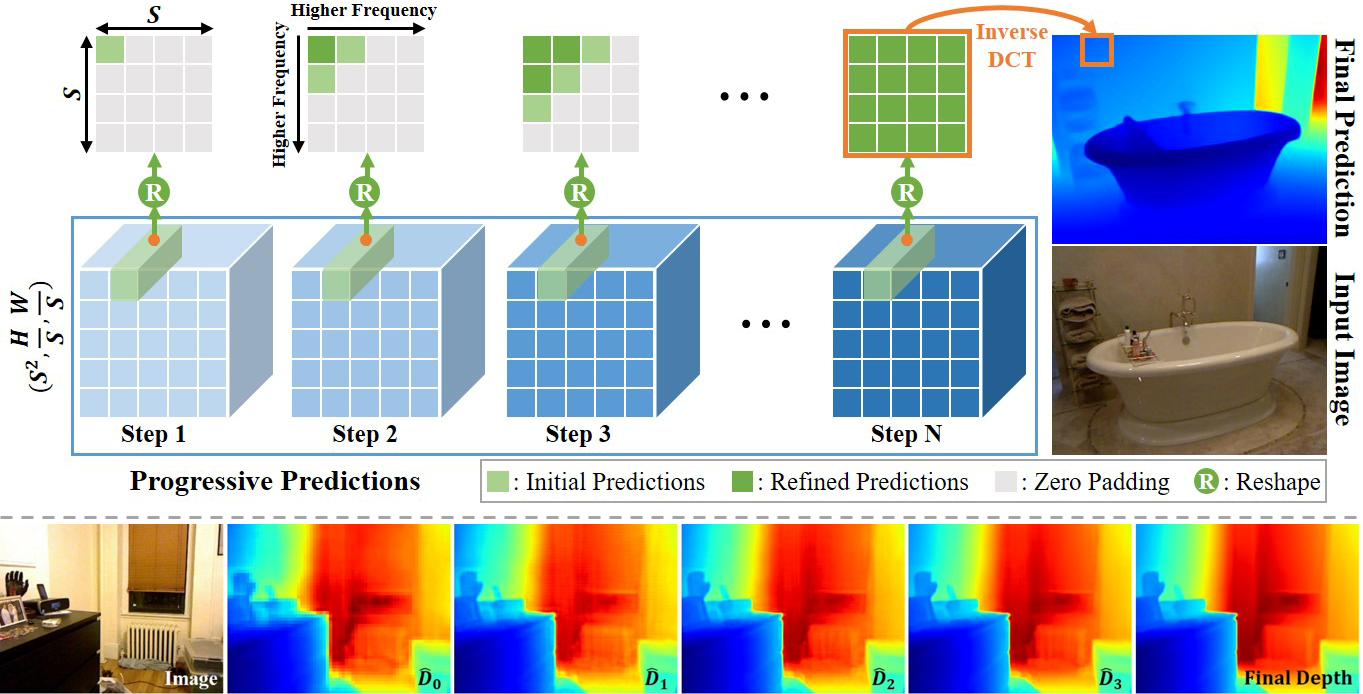
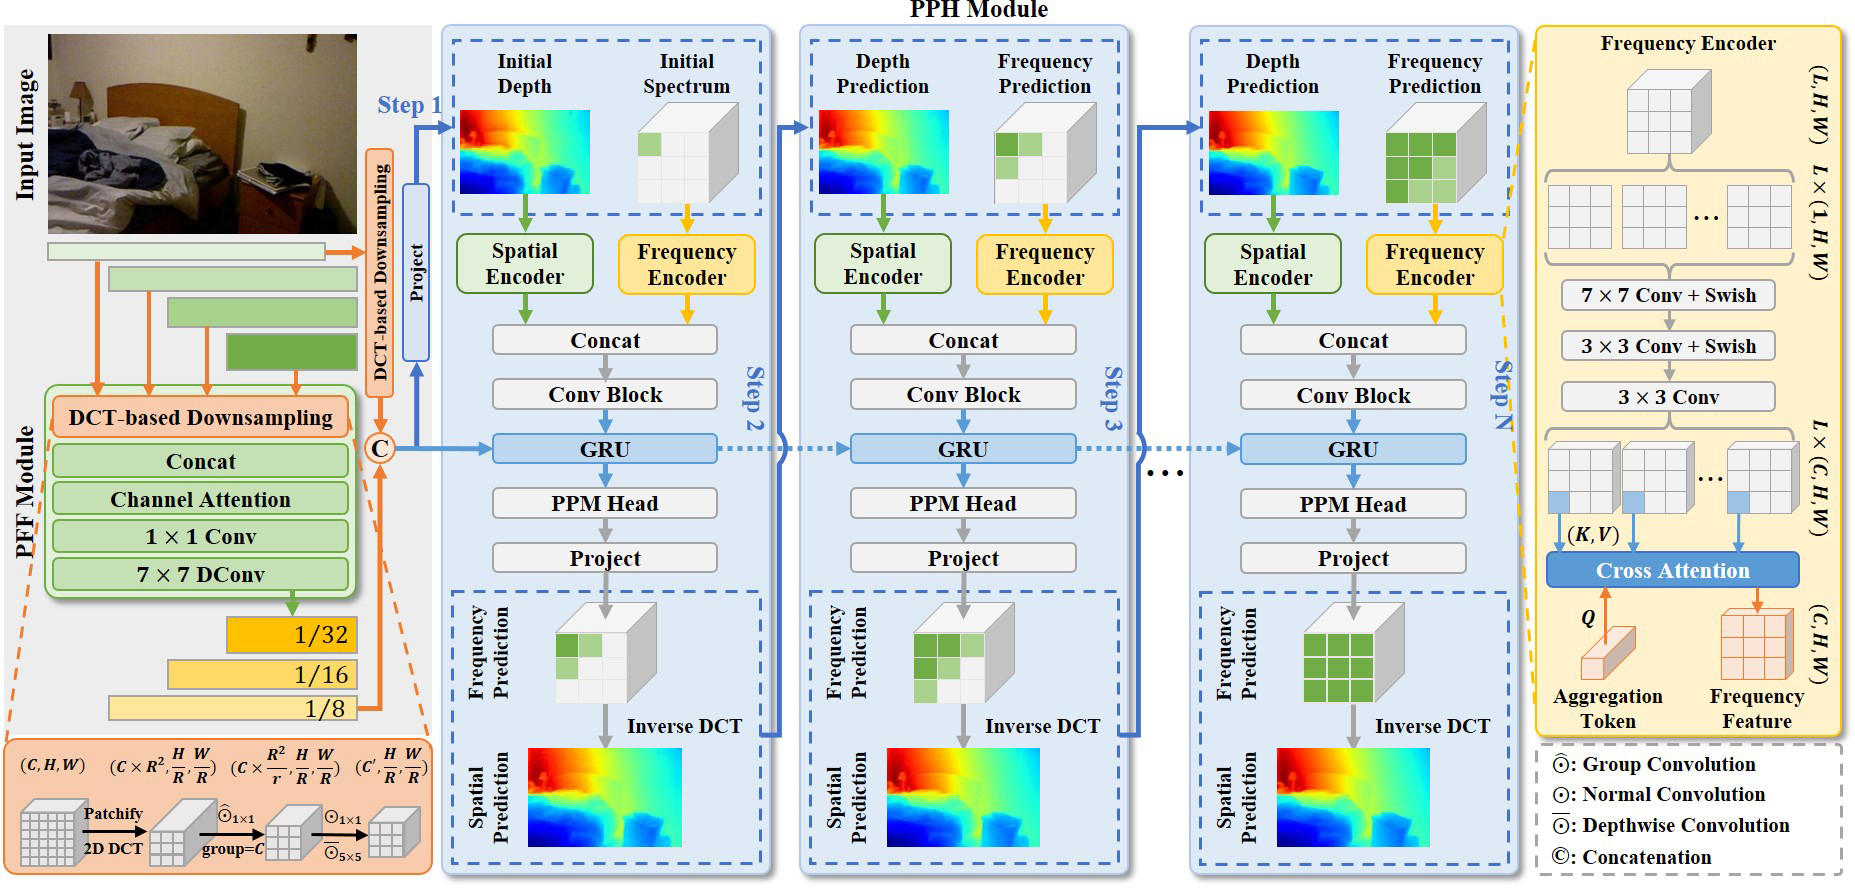
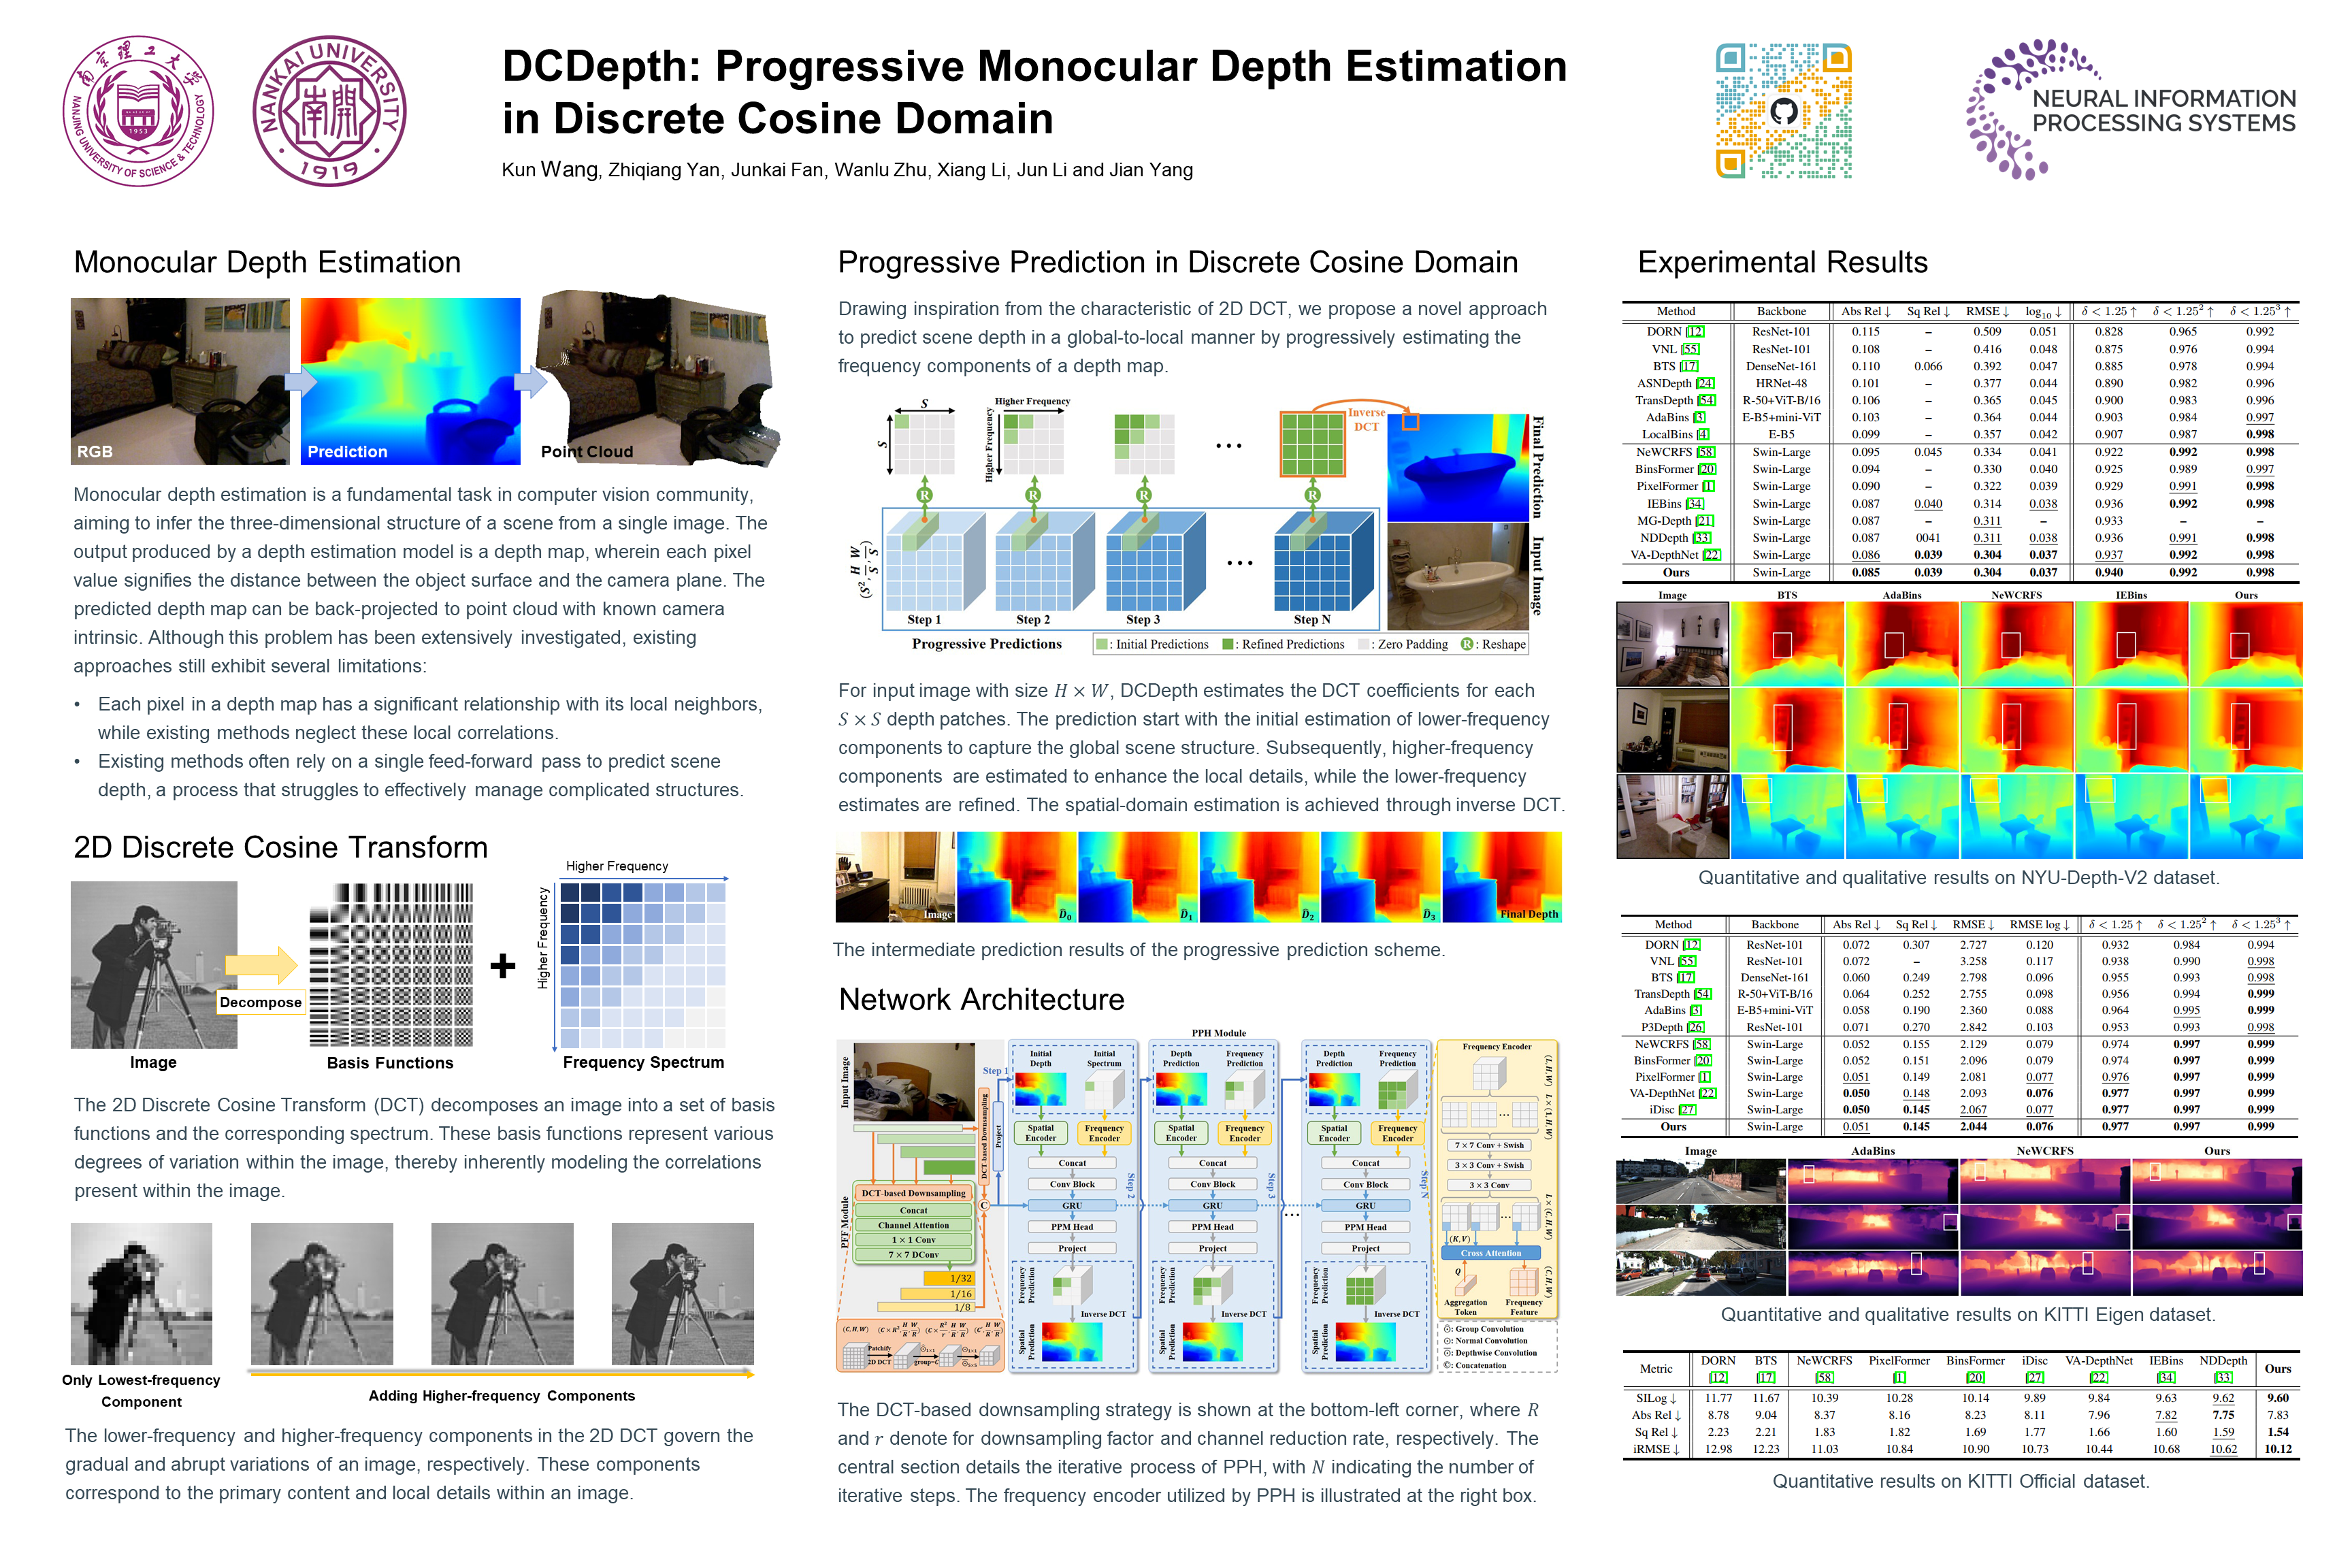
DCDepth redefines monocular depth estimation by moving it into the discrete cosine domain, where it models local correlations within depth patches. By exploiting frequency characteristics, DCDepth progressively estimates depth, starting with low-frequency components and then refining with high-frequency details, facilitating a global-to-local depth estimation approach.
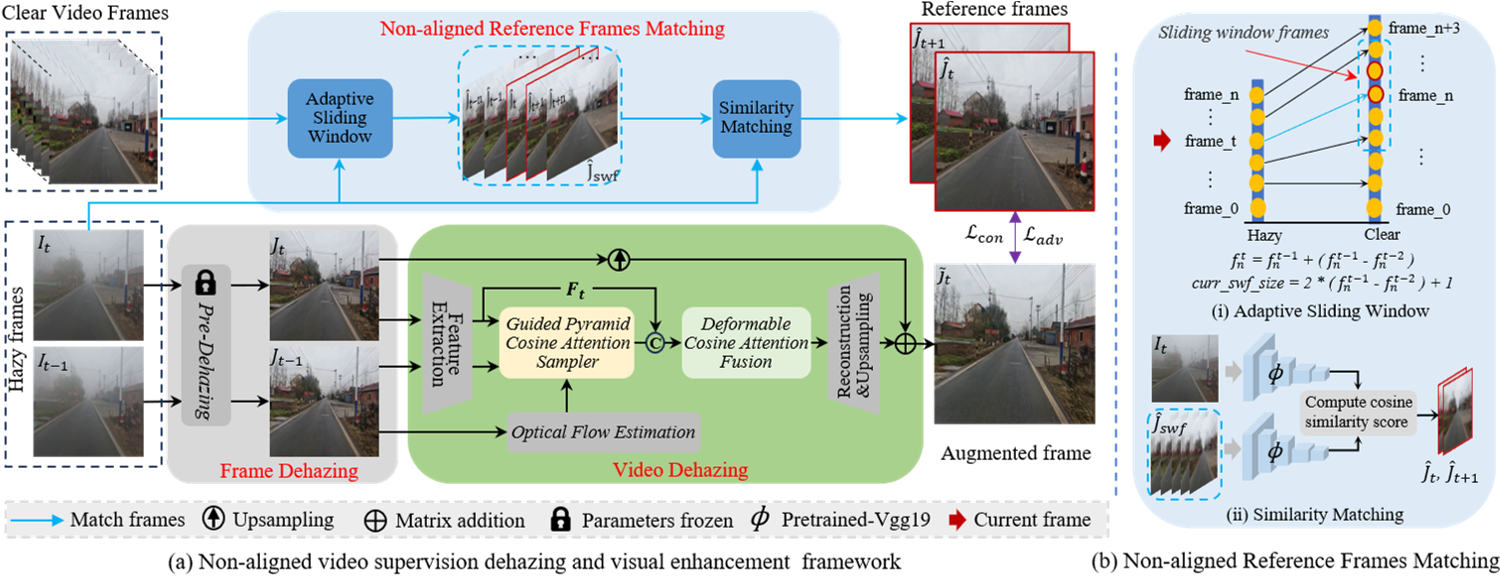
We present an innovative video dehazing framework for real-world driving scenarios, addressing temporal and spatial misalignment challenges with non-aligned hazy/clear video pairs and a reference frame matching module.
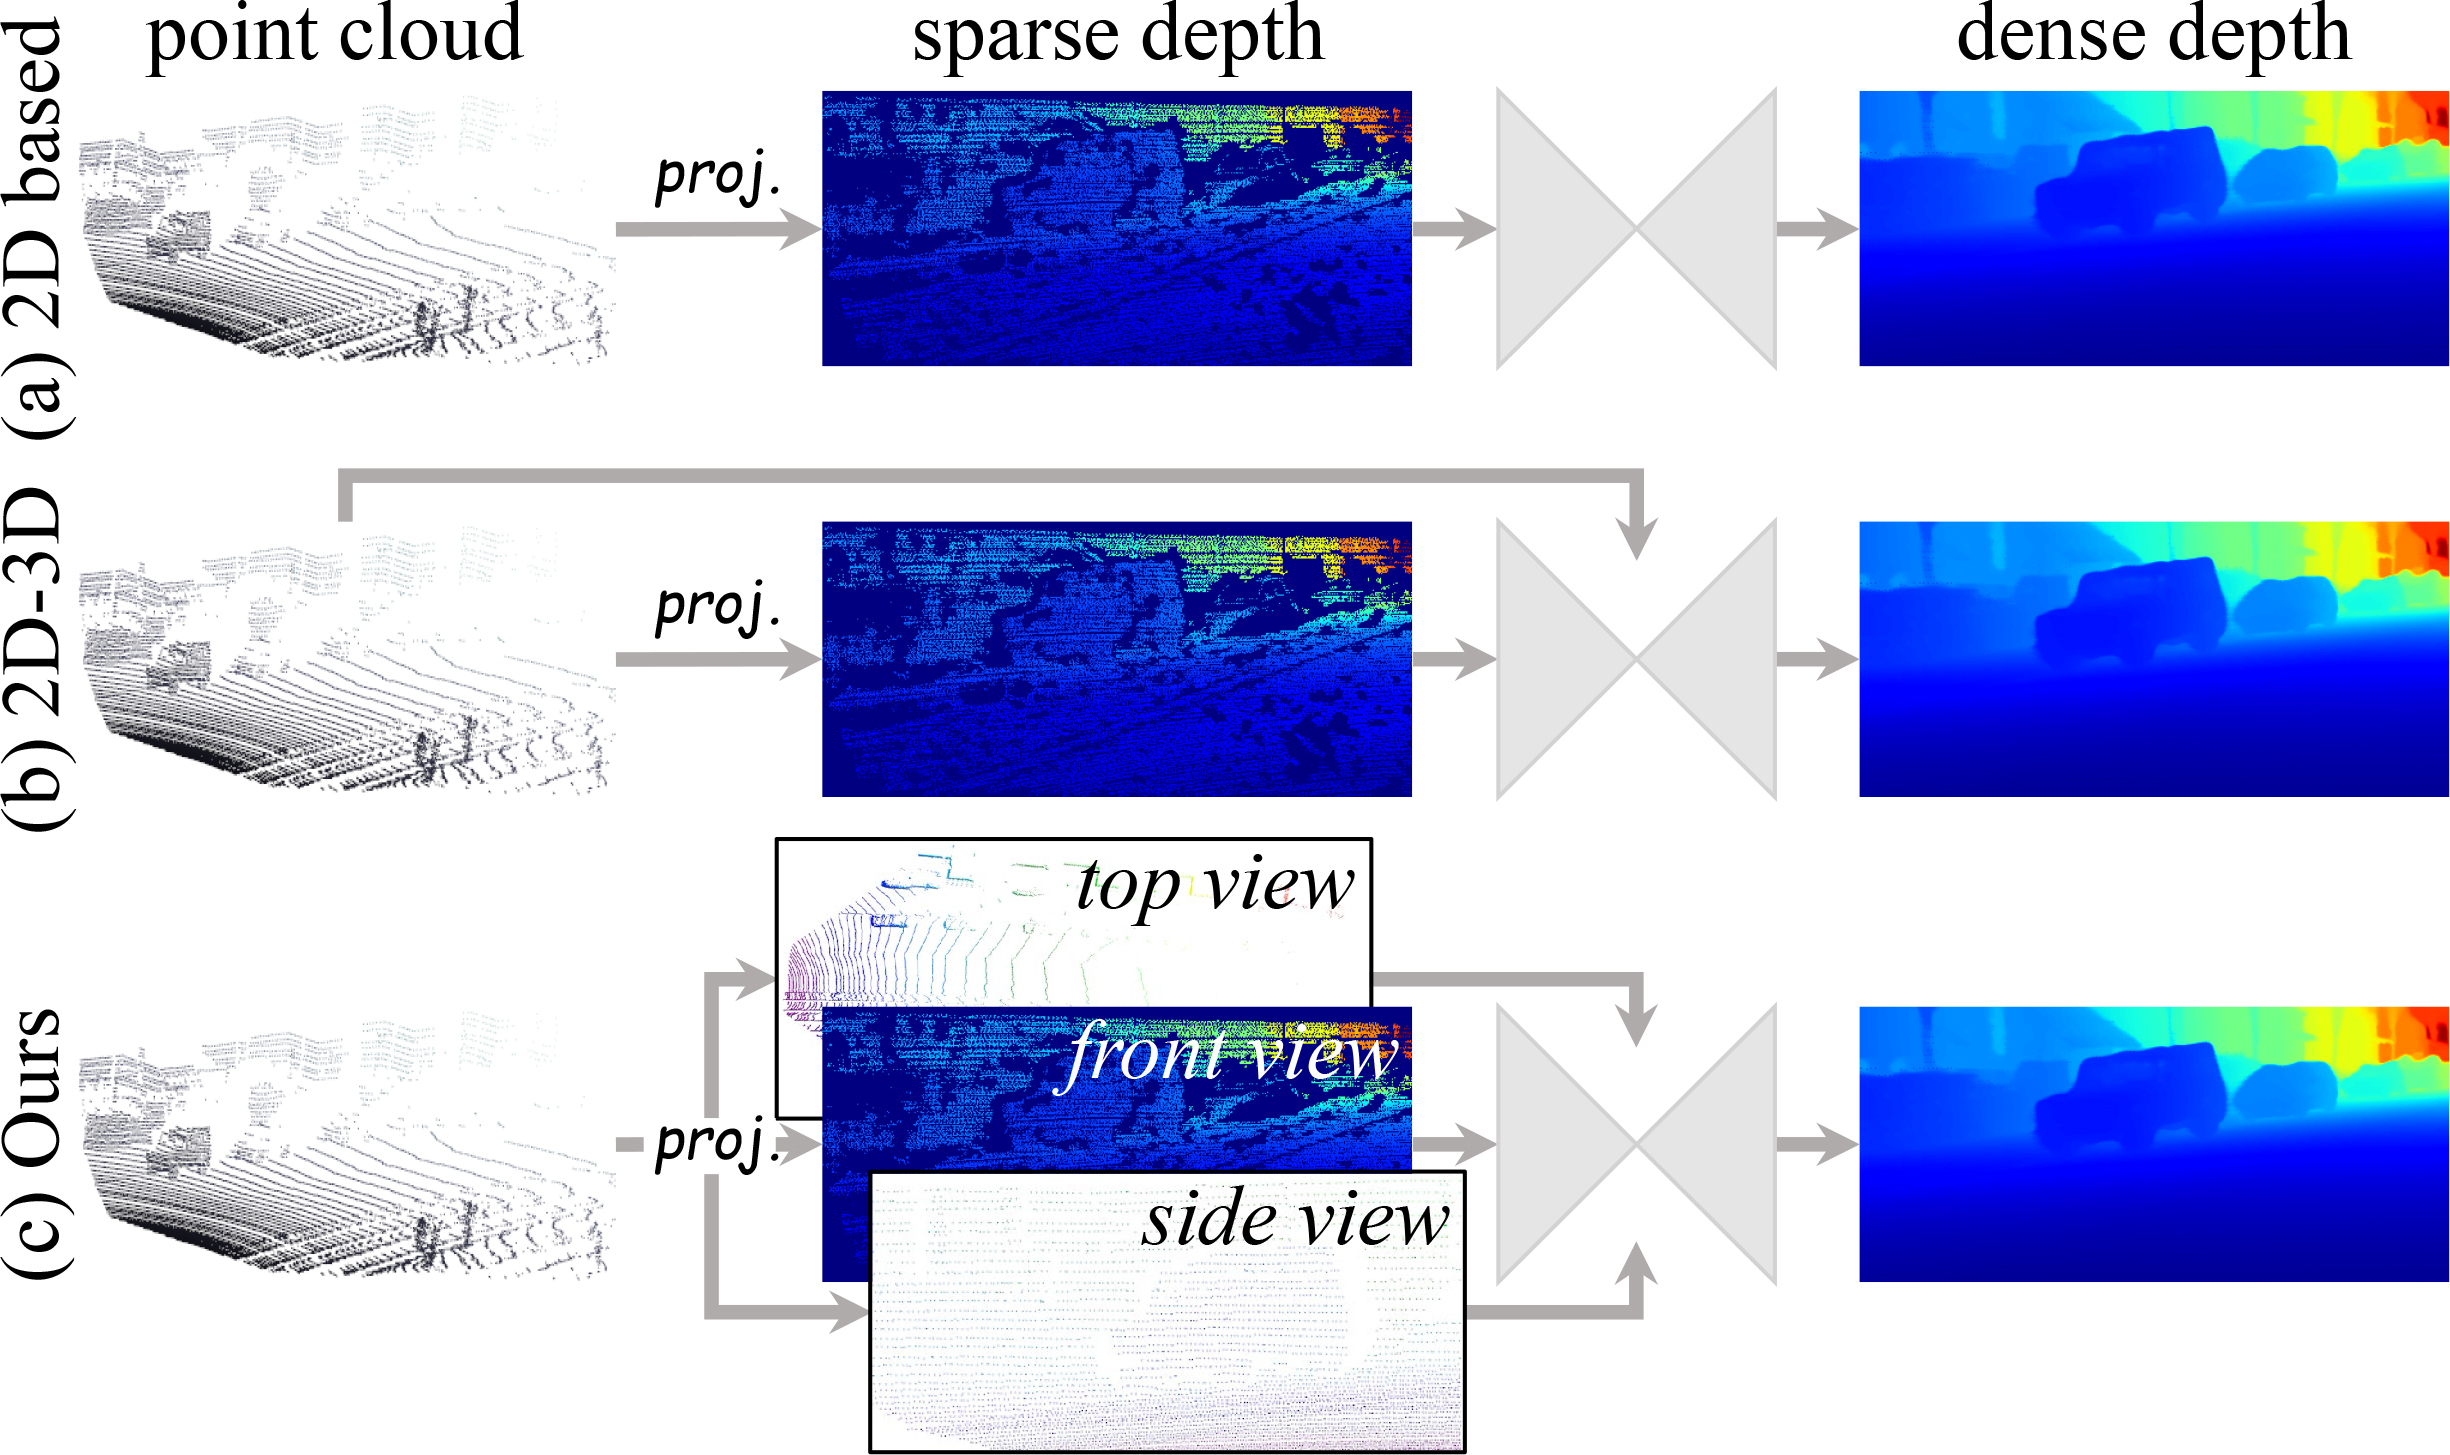
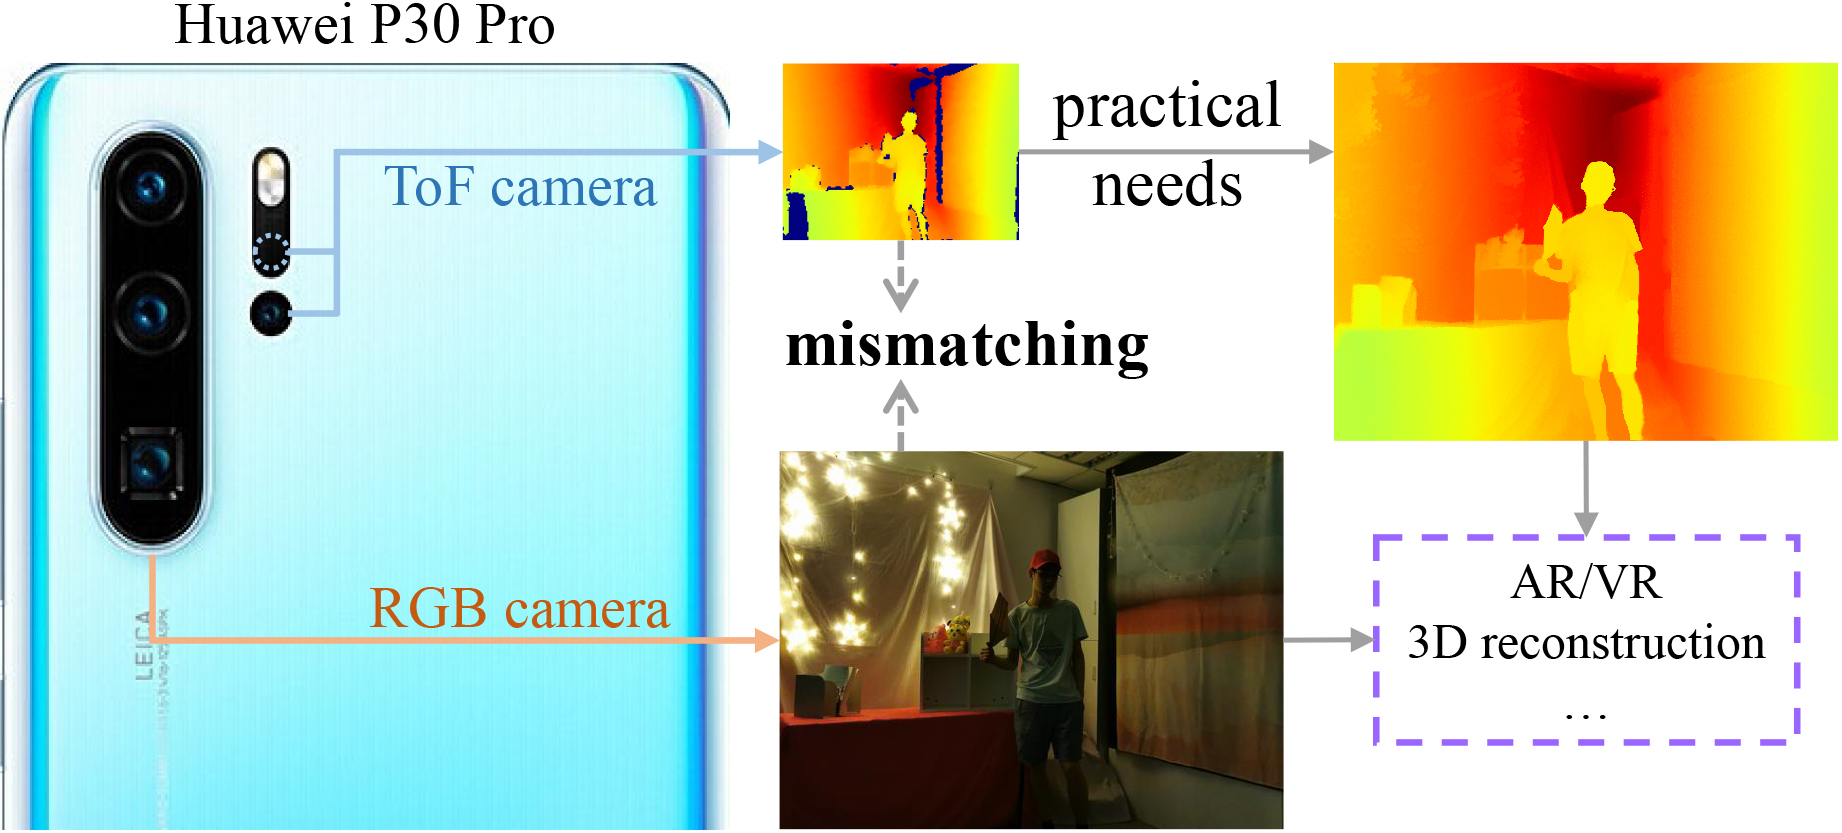
TPVD decomposes 3D point cloud into three views to capture the fine-grained 3D geometry of scenes. TPV Fusion and GSPN modules are proposed to refine the depth. Furthermore, we build a novel depth completion dataset named TOFDC, acquired by a smartphone equipped with a time-of-flight (TOF) sensor.
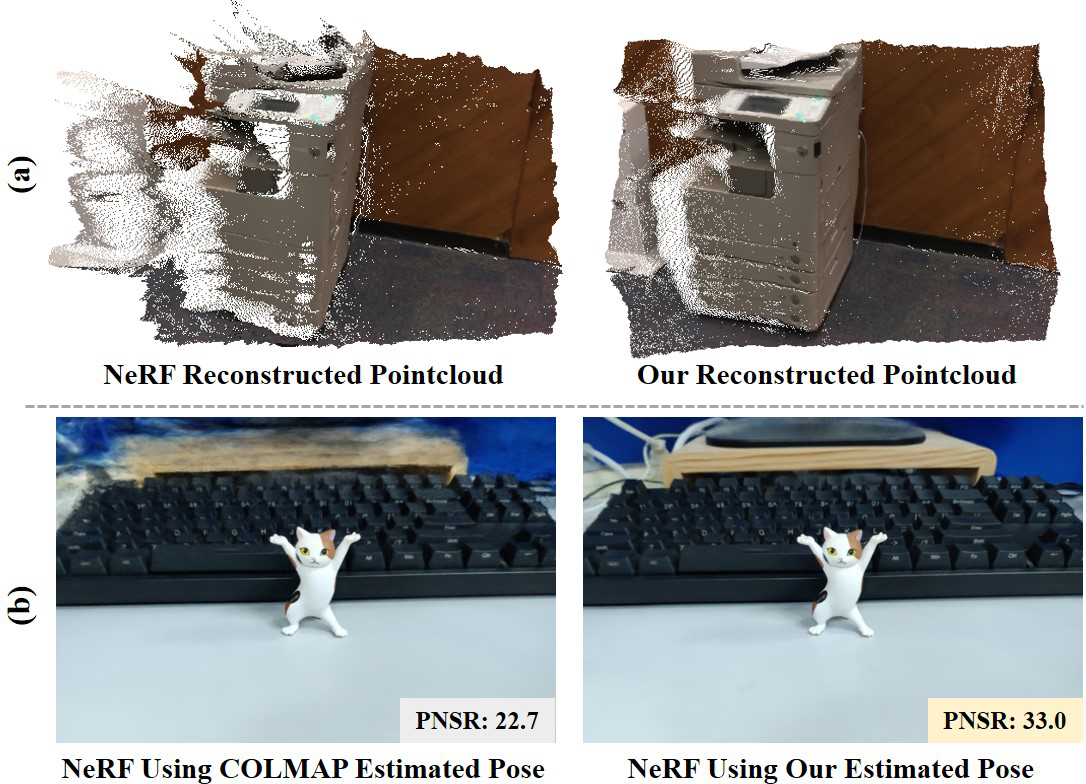
NeRF optimization frequently encounters local minima due to inaccurate camera poses and absent 3D supervision. AltNeRF employs an alternating optimization approach, starting with coarse depth and pose from a self-supervised estimator, to simultaneously refine camera pose, scene depth, and learn the NeRF representation, thereby substantially lowering the cost of high-quality NeRF creation.
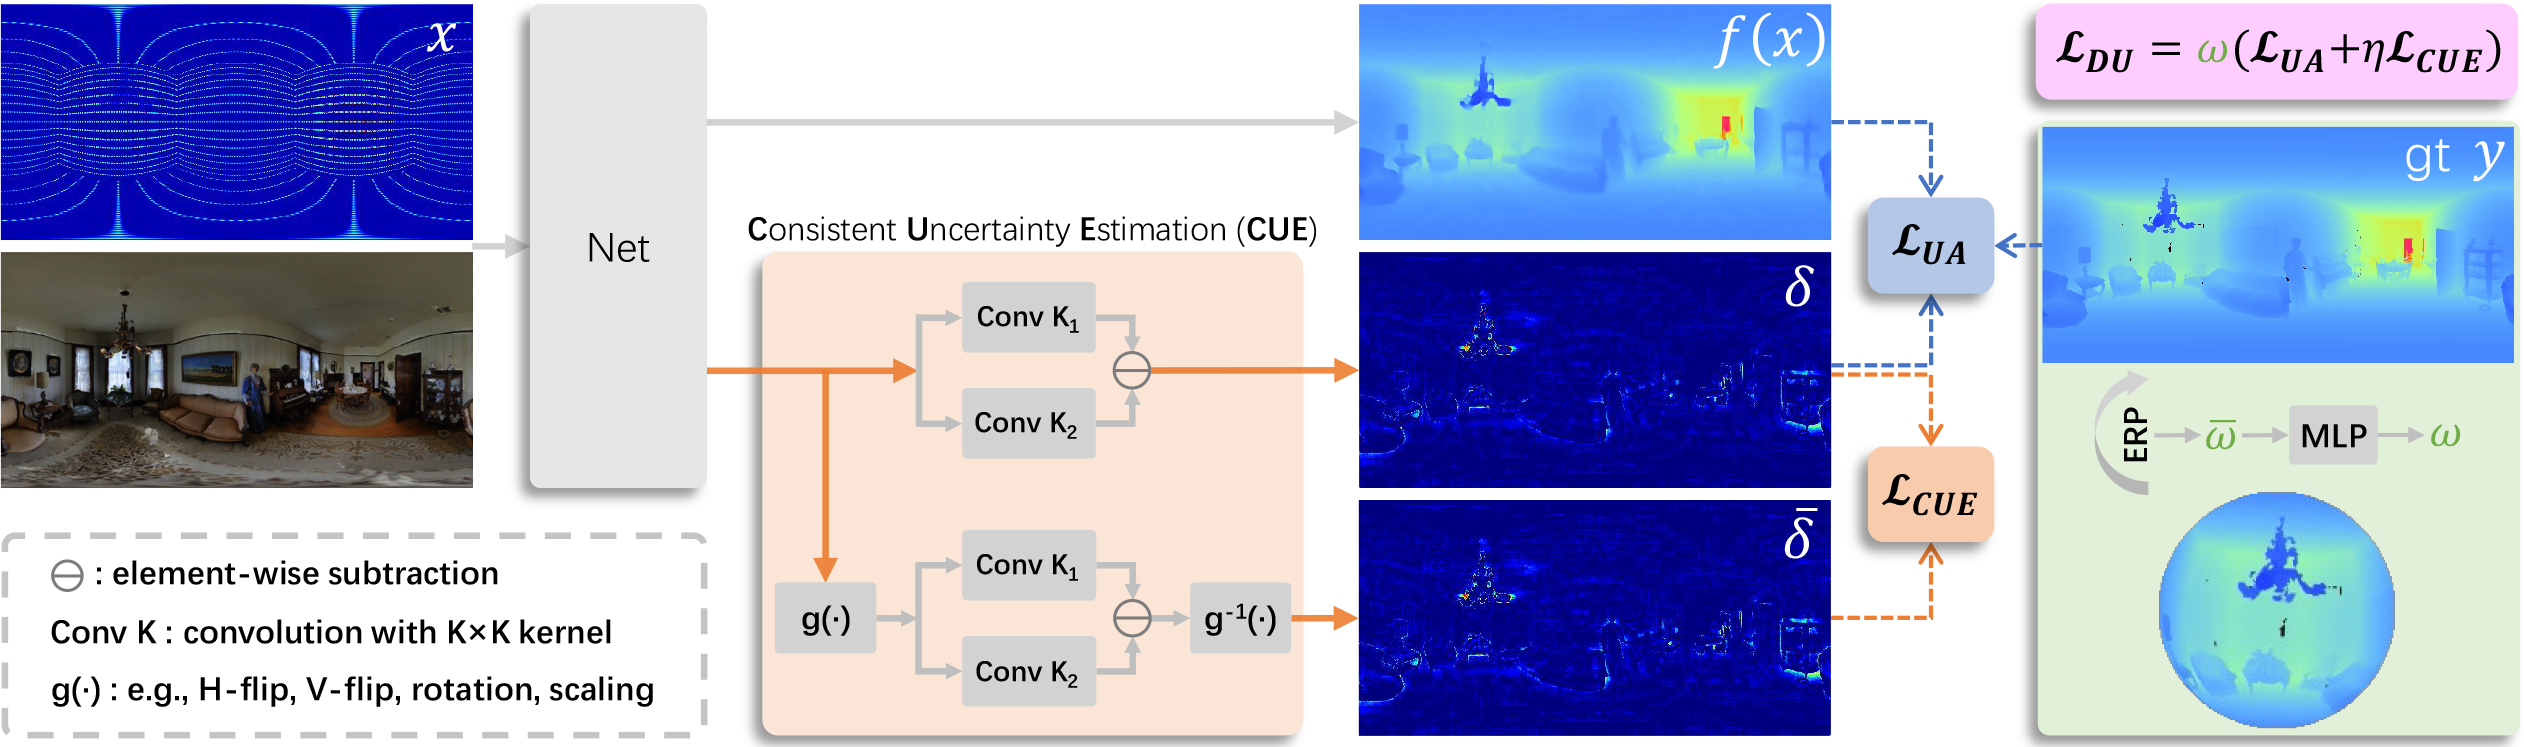
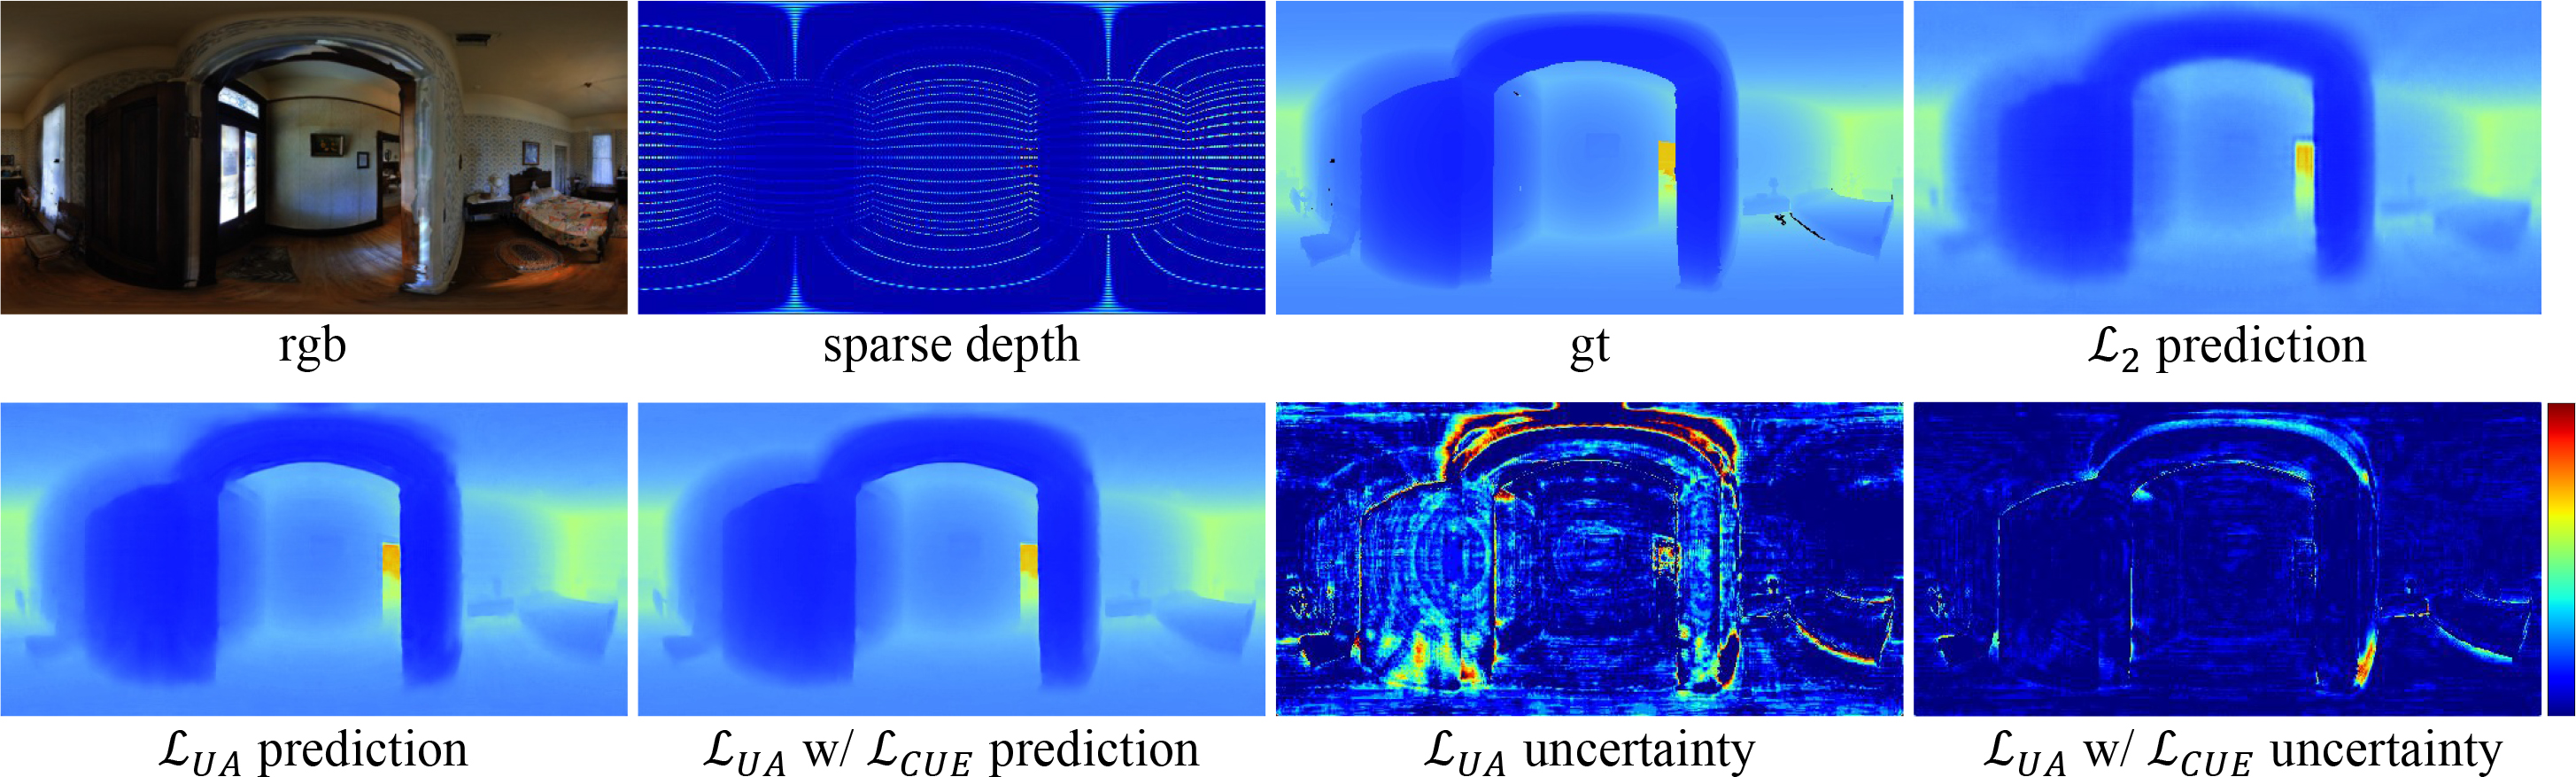
Standard MSE or MAE loss function is commonly used in limited field-of-vision depth completion, treating each pixel equally under a basic assumption that all pixels have same contribution during optimization. However, the assumption is inapplicable to panoramic data due to its latitude-wise distortion and high uncertainty nearby textures and edges. To handle these challenges, this paper proposes the distortion and uncertainty aware loss (DUL) that consists of a distortion-aware loss and an uncertainty-aware loss.
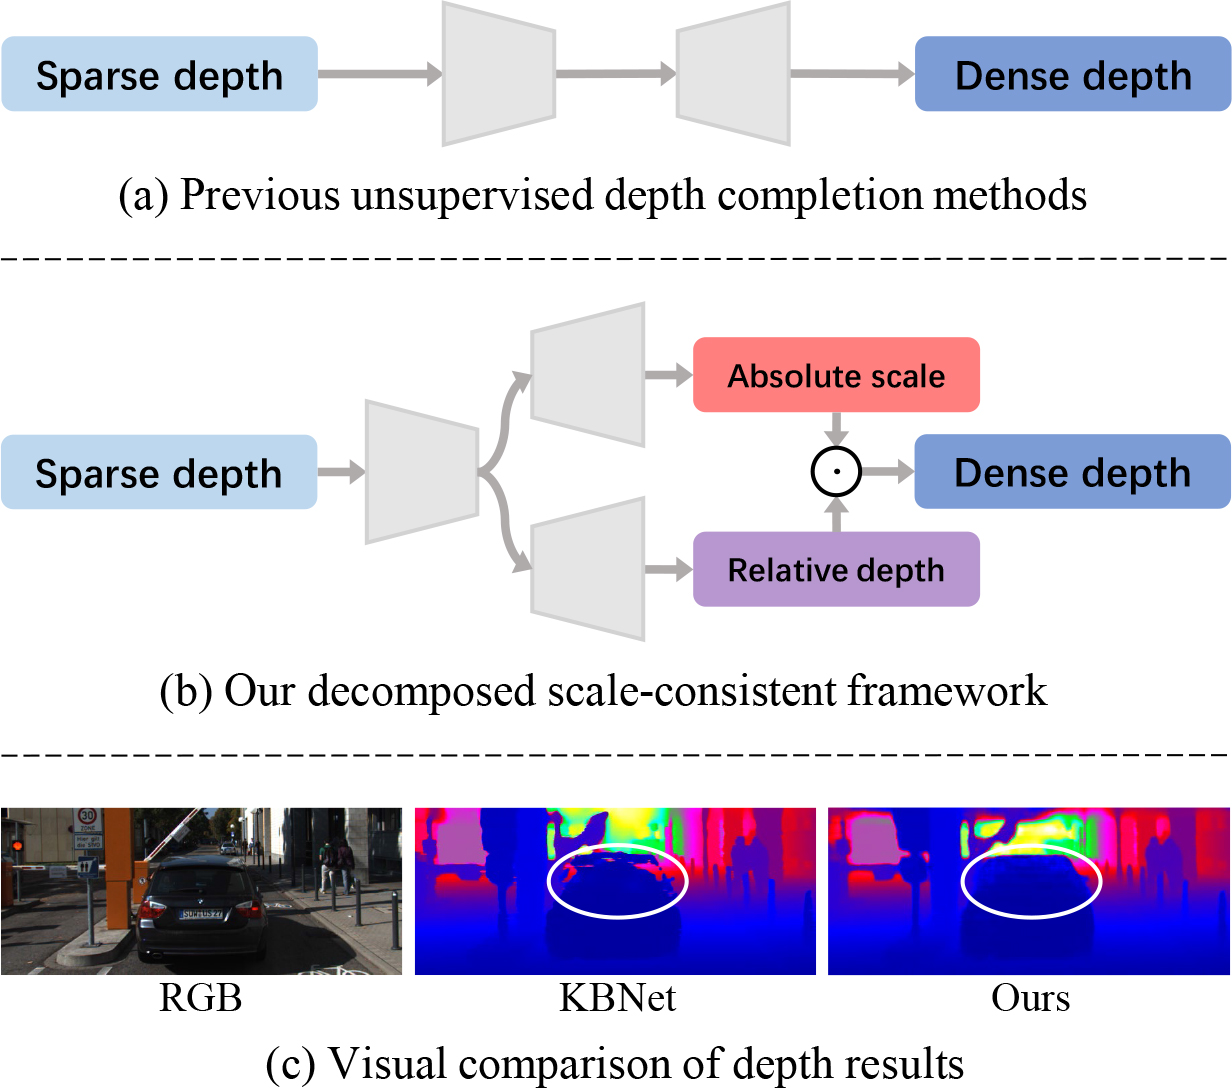
DesNet first introduces a decomposed scale-consistent learning strategy, which disintegrates the absolute depth into relative depth prediction and global scale estimation, contributing to individual learning benefits. Extensive experiments show the superiority of DesNet on KITTI benchmark, ranking 1st and surpassing the second best more than 12% in RMSE.
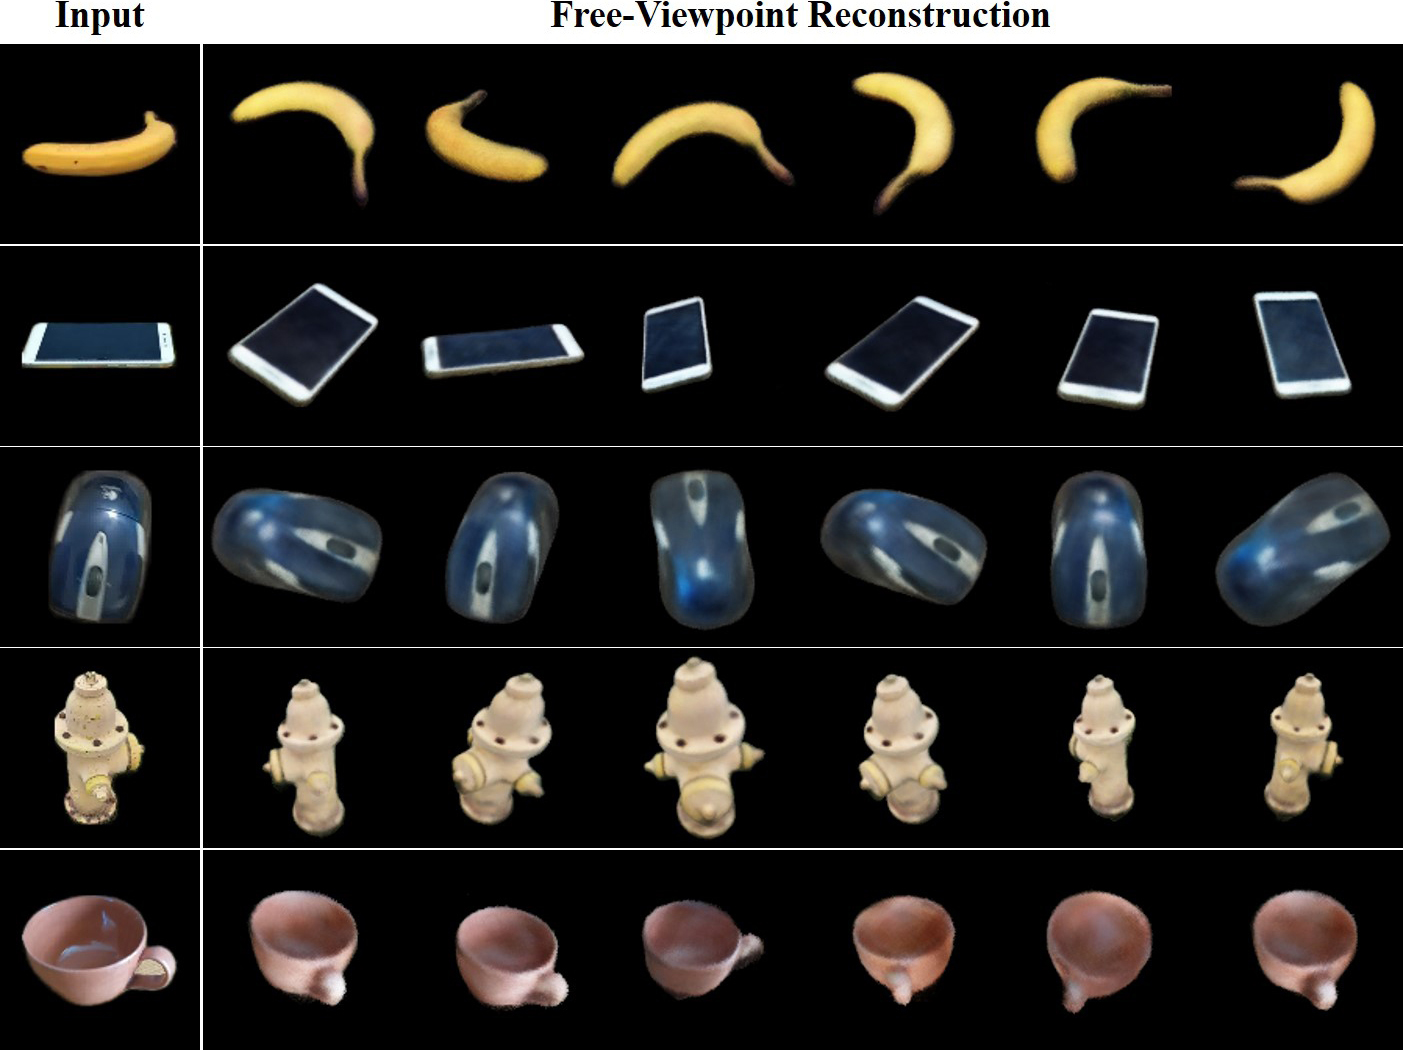
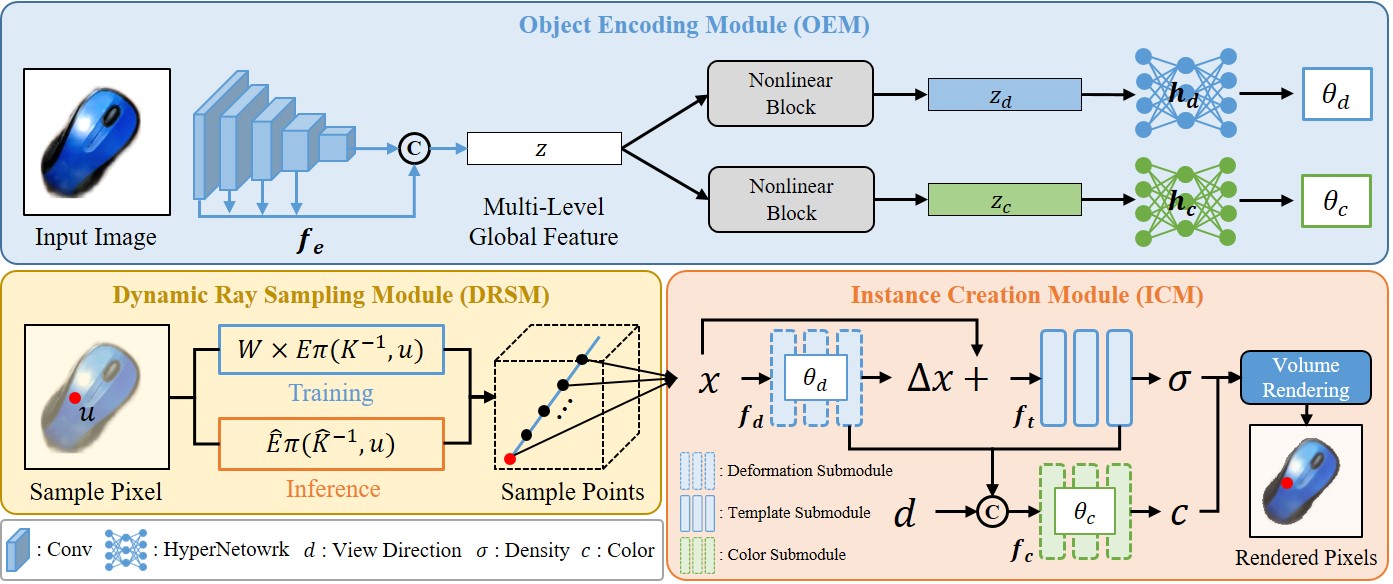
VRF introduces a novel framework for reconstructing category-specific objects from a single image without requiring known camera intrinsics, while also being robust against occlusions. Leveraging a global representation, coordinate-consistent modeling, contrastive learning-based pretraining, and hyper-network-based rendering, VRF significantly outperforms prior methods in both reconstruction performance and efficiency on real-world datasets.
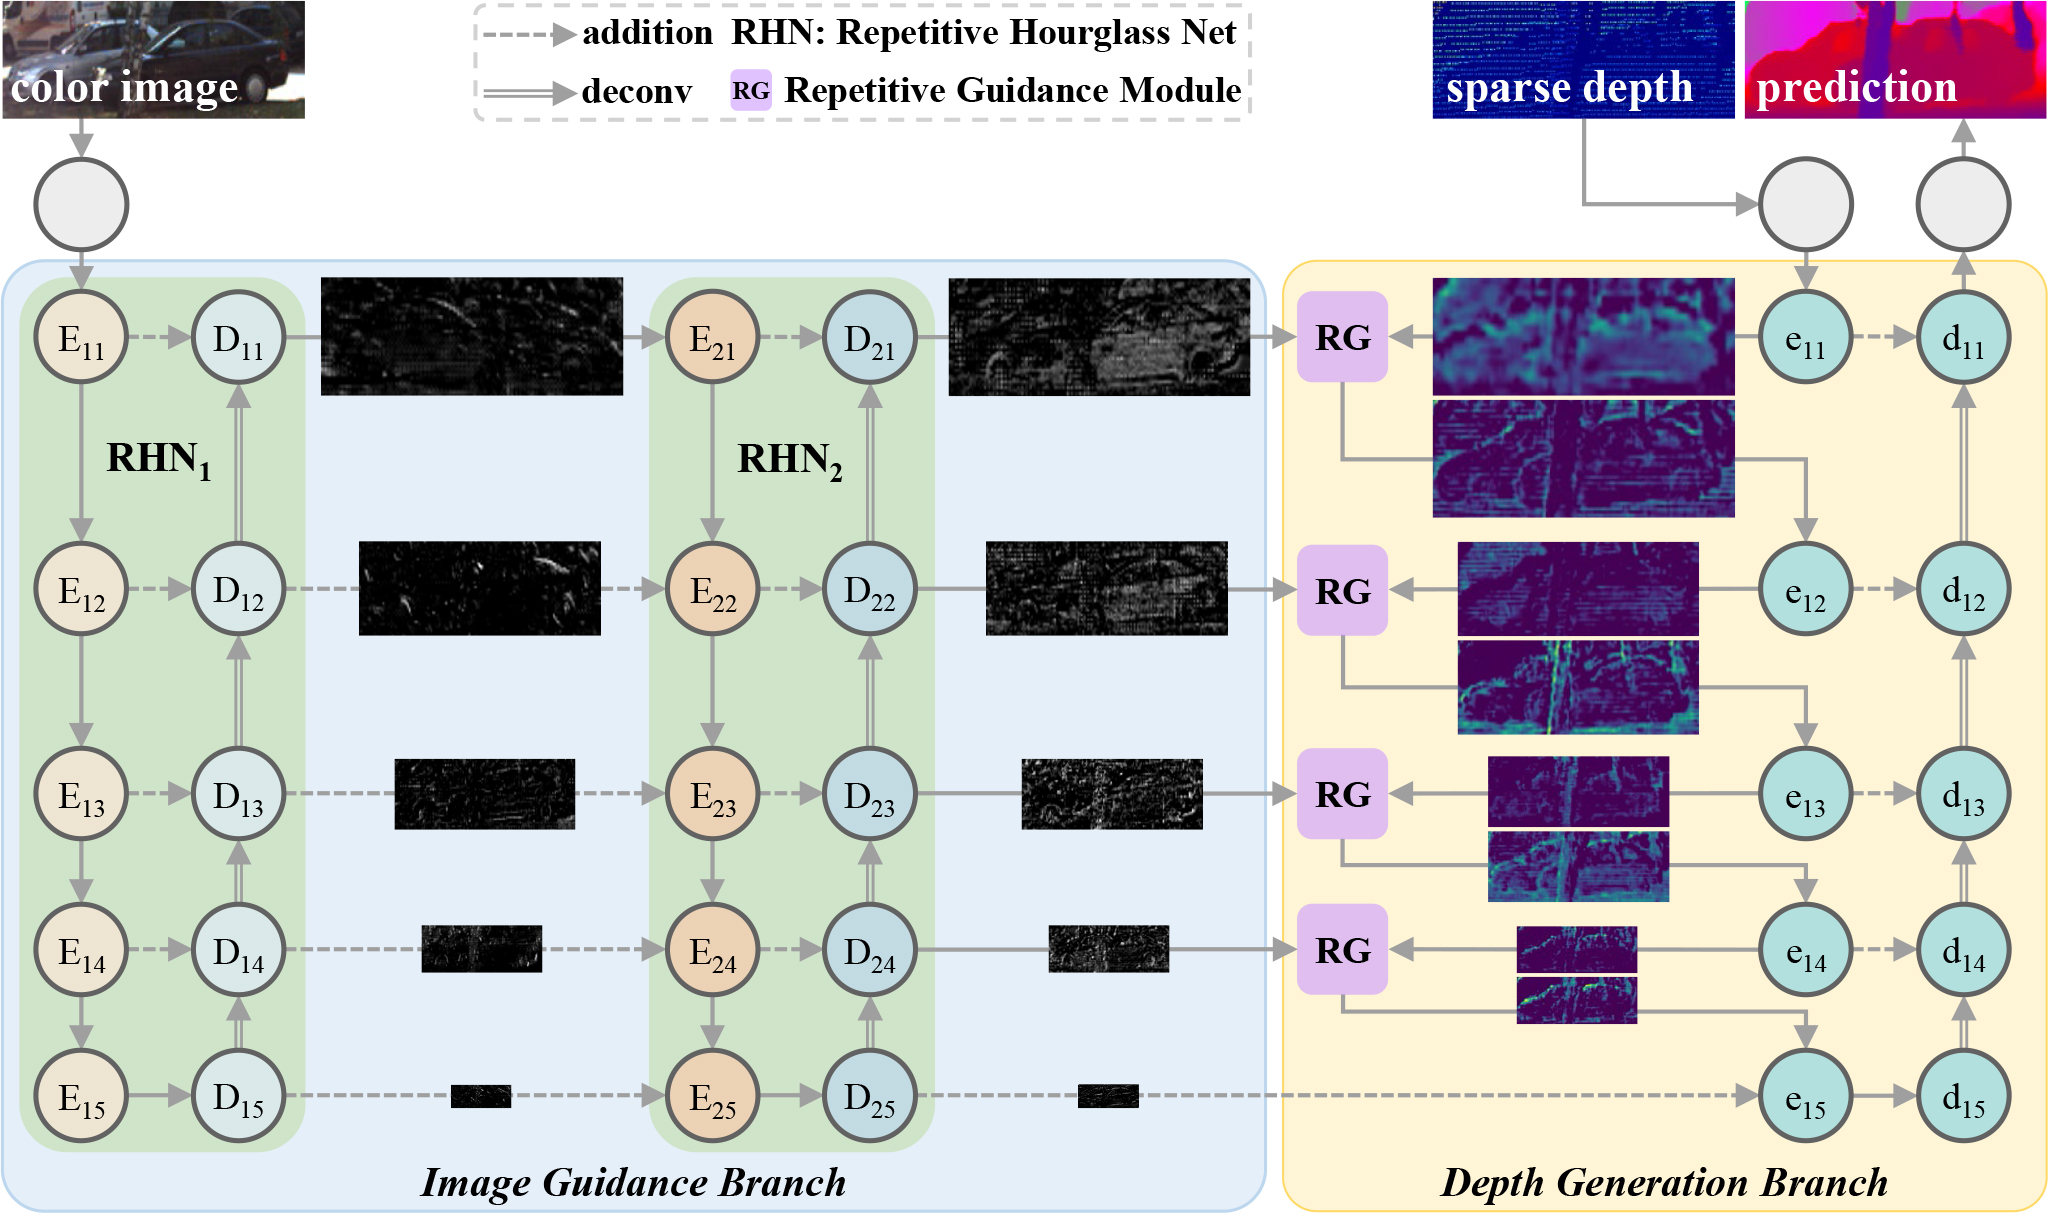
RigNet explores a repetitive design for depth completion to tackle the blurry guidance in image and unclear structure in depth. Extensive experiments show that RigNet achieves superior or competitive results on KITTI benchmark and NYUv2 dataset.
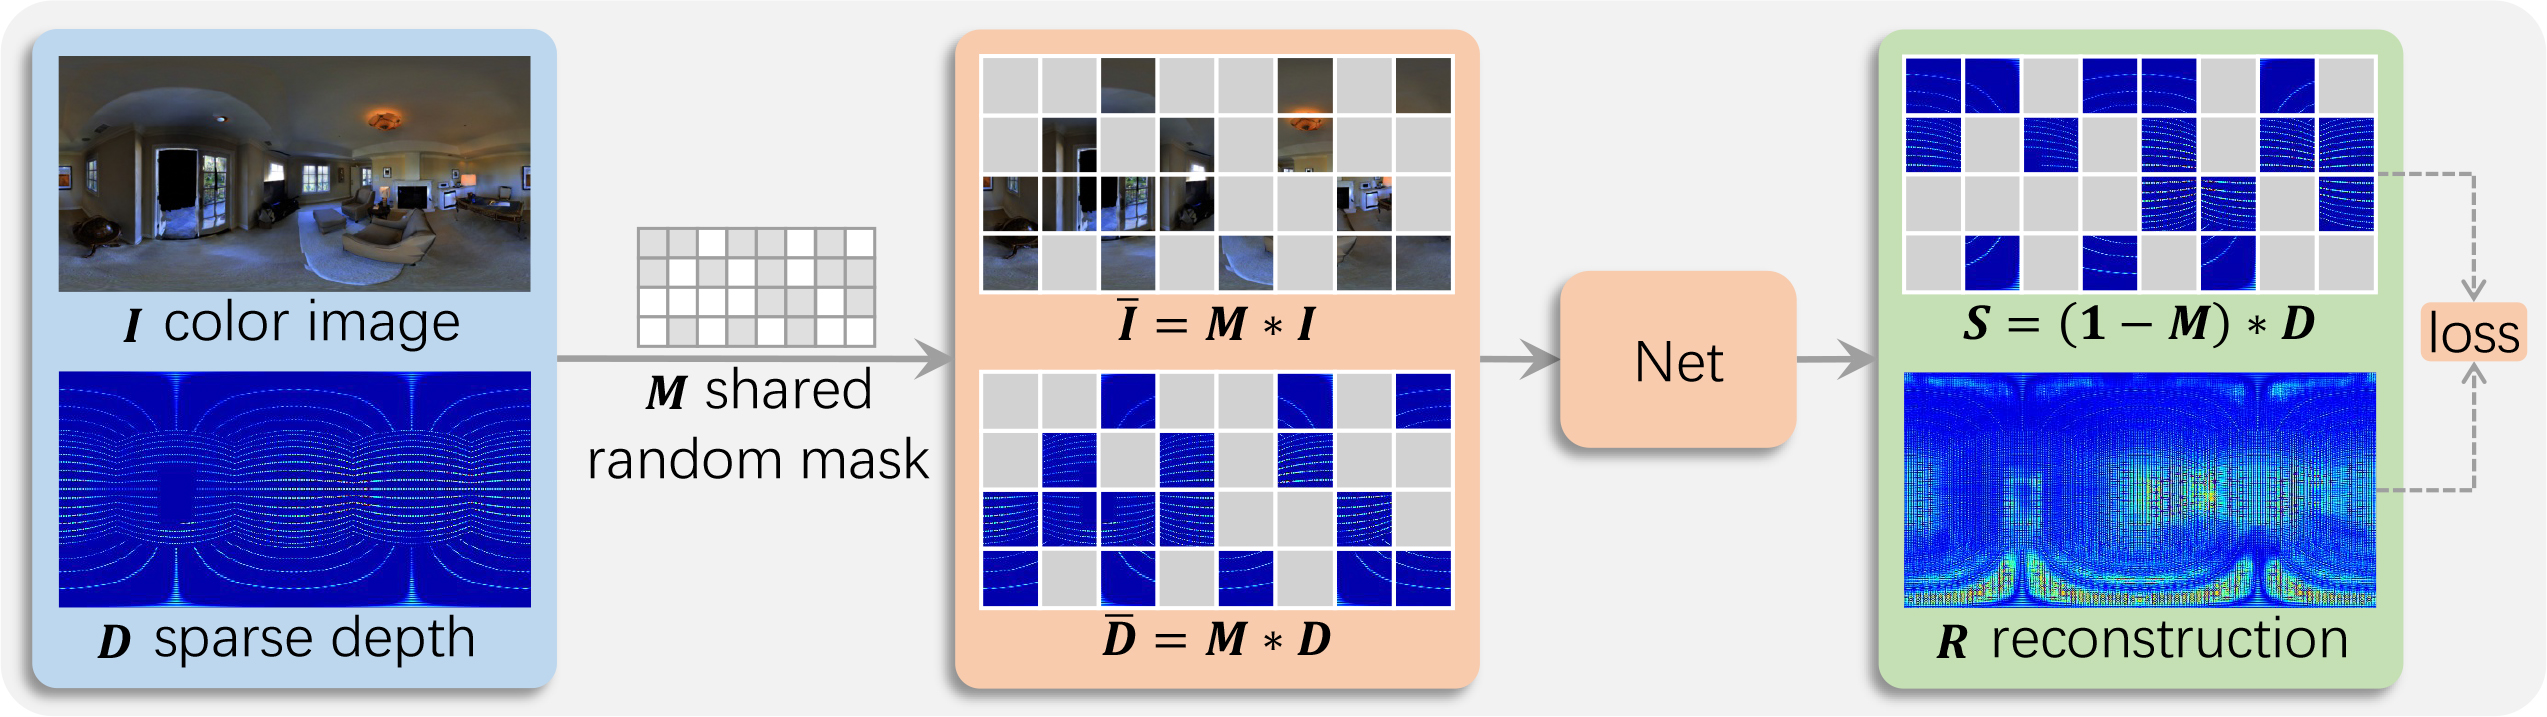
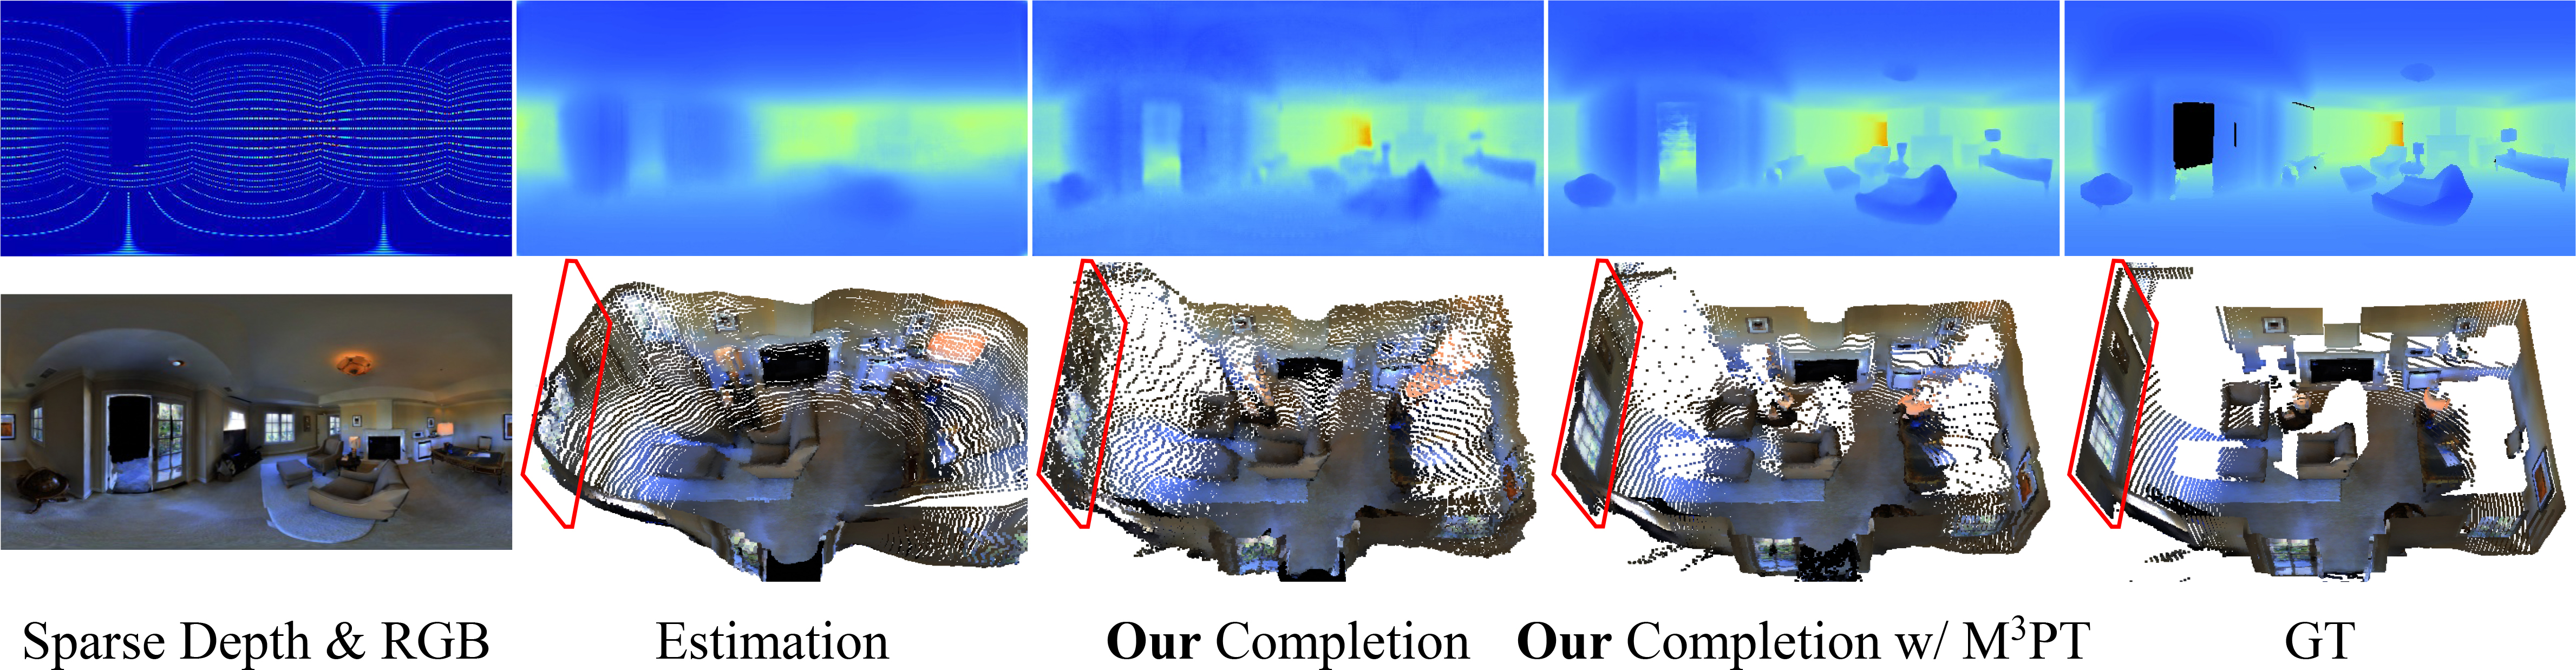
For the first time, we enable the masked pre-training in a Convolution-based multi-modal task, instead of the Transformer-based single-modal task. What's more, we introduce the panoramic depth completion, a new task that facilitates 3D reconstruction.
Motivated by pratical applications, this paper introduces a new task, i.e., incomplete depth super-resolution (IDSR), which recovers dense and high-resolution depth from incomplete and low-resolution one.
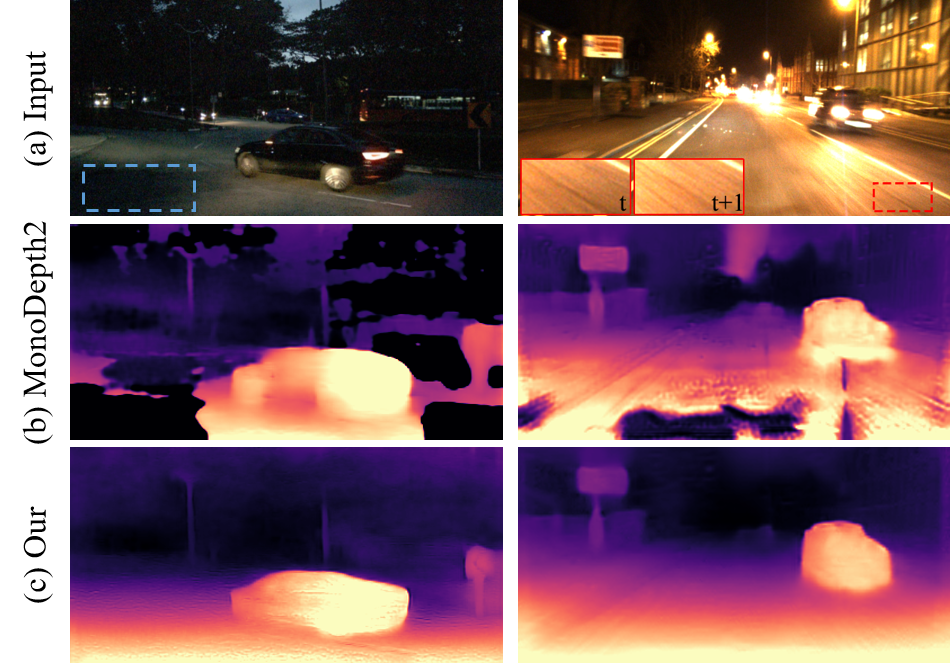
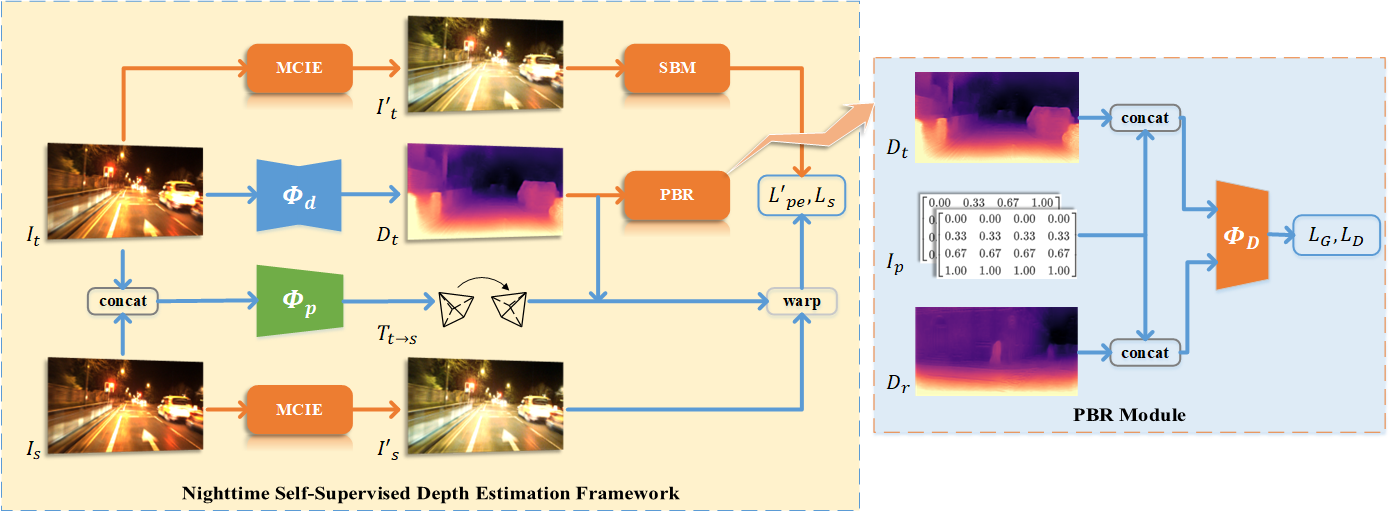
RNW first introduces a self-supervised monocular depth estimation framework that directly trained on the real-world nighttime images. It leverages distribution knowledge from unpaired depth maps to prevent incorrect model training, and further improves the prediction accuracy with brightness-consistent image enhancement and statistics-based pixel removel.
Academic Activities
Area Chair
2026ICME
Guest Editor
2026Sensors — Special Issue: Sensor Applications in 3D Sensing, Depth Perception and Reconstruction